Adding Real-Time Web Retrieval to LangChain and LlamaIndex Without Breaking Your Context Budget
Live web search works only if you enforce strict token limits before the prompt gets crowded.
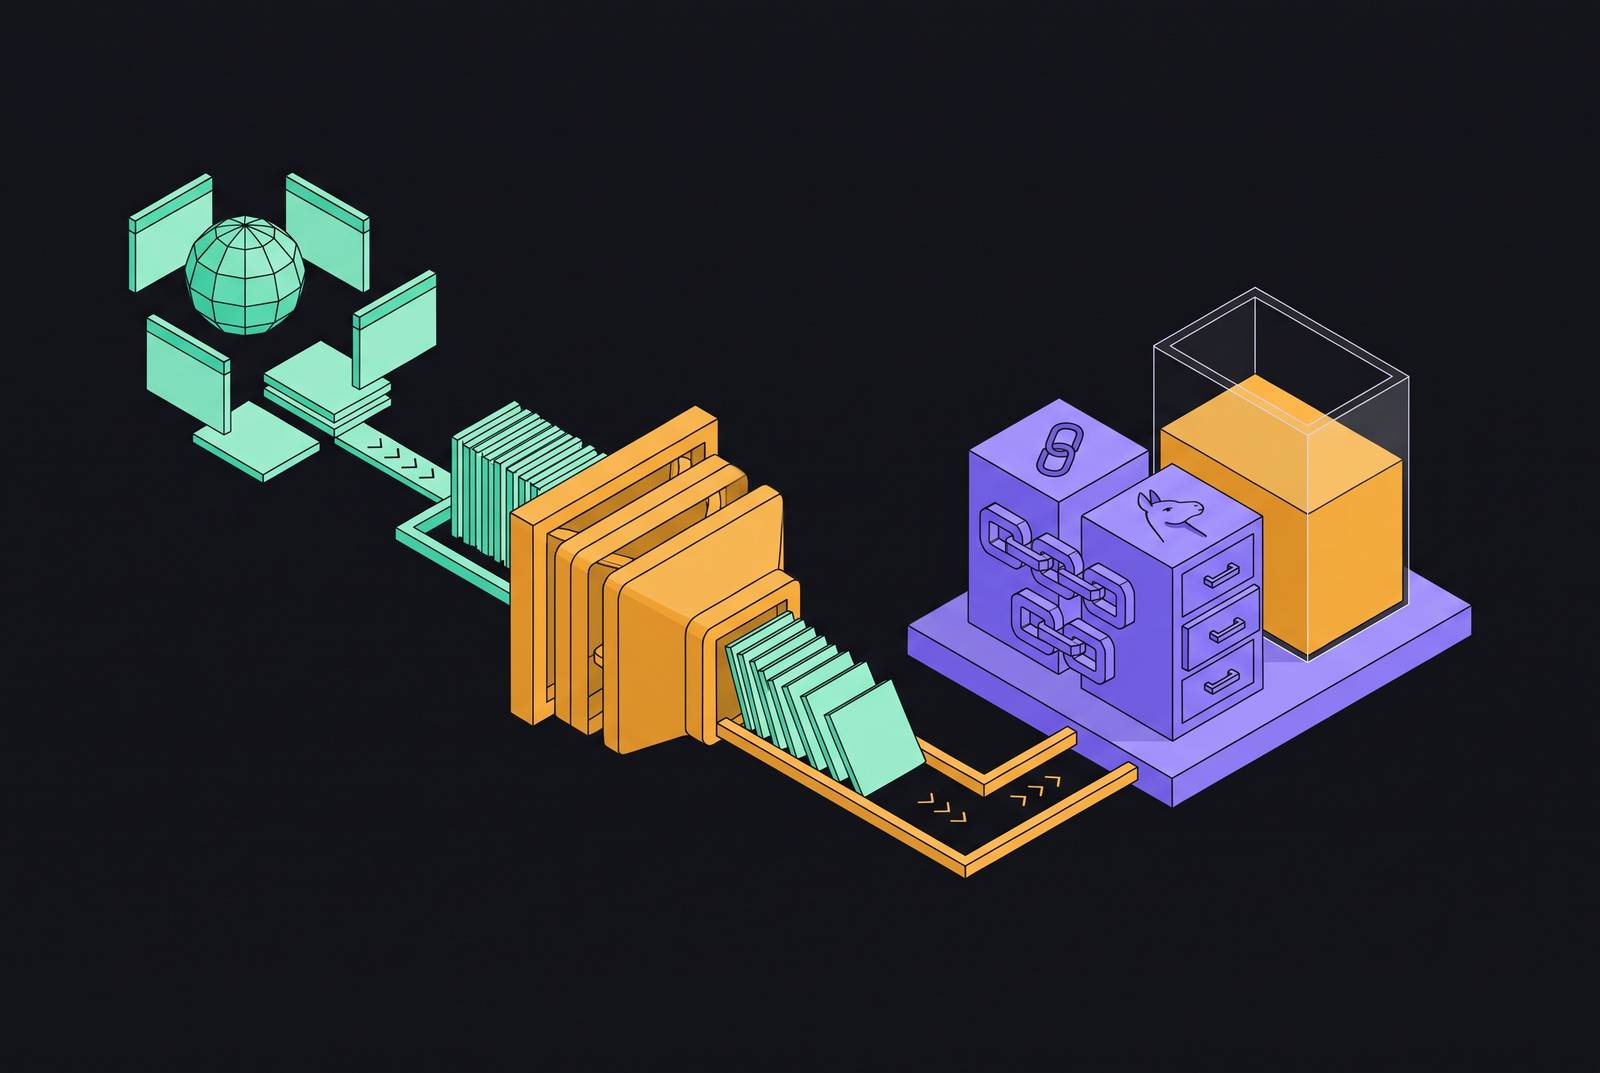
Adding real-time web retrieval to LangChain or LlamaIndex requires more than connecting a search endpoint. A web search API for AI agents and RAG pipelines should supply fresh, ranked, machine-ready content, while the application enforces a fixed retrieval budget before prompt assembly. The engineering task is to select, filter, and shape evidence so that live information improves answers without crowding out the context needed to reason.
Why embedding-only RAG drifts and what web retrieval is supposed to fix
An embedding index knows only the material it contains. Knowledge cutoff drift leaves it behind changes made after the last build, coverage gaps hide topics never crawled, and stale embeddings can surface cached snippets that contradict live pages. Re-indexing cuts some of that lag, but the index still knows only what it contains. For time-sensitive queries, coverage and currency remain separate requirements.
The model’s training cutoff compounds those limits when a question concerns recent events, library versions, CVEs, or regulatory changes. Without current evidence, an answer may be invented or withheld. Embedding-only RAG is therefore incomplete for these queries. SERP grounding supplies the targeted fix by fetching the live web at query time and feeding that evidence into the same retrieve-and-rerank pipeline as embedded documents.
How LangChain and LlamaIndex divide retrieval responsibility differently
LangChain treats the application as a directed graph of tasks, with strengths in tool orchestration, multi-step agent workflows, and conversational flows. LangGraph adds durable execution, interrupts, and state persistence. LlamaIndex instead centers the application on a searchable graph of document nodes, with parsing, indexing, query engines, and evaluation tooling. The distinction determines where retrieval controls belong. Systems using both can place retrieval and indexing in LlamaIndex while LangChain and LangGraph decide when to retrieve, invoke another tool, or answer directly.
The integration paths are already well defined. In LangChain, a web search source can enter as a custom BaseRetriever subclass and combine with a vector retriever through EnsembleRetriever. In LlamaIndex, a web search reader wraps the API and returns Document objects, with SubQuestionQueryEngine supporting complex query decomposition. These patterns establish where evidence enters the application. They do not, by themselves, decide how much of that evidence deserves space in the prompt.
Why adding a web retrieval source immediately pressures the context window
The common failure is quiet degradation. Useful facts become buried or truncated as web snippets, vector store hits, MCP tool descriptions, conversation history, and system prompts compete for finite space. Even a model with a very large context window operates under retrieval-layer constraints, because the serving infrastructure also bounds how much retrieved content a generation call can consume.
Returning the maximum number of search results uses tokens whether or not the query needs that much evidence. Arbitrary character splits break up logical units, while embedding-similarity order can put less useful material ahead of evidence that helps with the task. These choices dilute attention even before the nominal token limit is reached.
Deciding which queries actually need live web retrieval
A freshness classifier checks whether the query needs current information, so web content stays out of the pipeline when it is not needed. A lookup table of freshness-sensitive categories, including security CVEs, package versions, prices, regulatory changes, and recent events, provides a recommended starting point. A small LLM can score freshness sensitivity when that table proves insufficient.
For example, “what does useEffect do?” can route to the vector store, while “latest CVE for Express?” should trigger live retrieval, either alongside the indexed lookup or on its own. That distinction also shapes source weighting. LangChain’s EnsembleRetriever can weight web evidence higher for freshness-sensitive queries and vector evidence higher for evergreen queries when both sources participate. Its weights parameter can change with the need for fresh evidence. In LlamaIndex, SubQuestionQueryEngine can decompose a complex question so that each sub-query is independently classified and only those needing current evidence trigger a web fetch.
Allocating a fixed token budget across retrieval sources before content reaches the LLM
Once retrieval is warranted, the application needs an explicit allocation. A fixed retrieval block in the available context can be split between vector results and web results, with hard caps applied before prompt assembly. The allocation must coexist with system instructions, conversation history, and tool descriptions rather than treating the entire window as available evidence space. Source limits make that division enforceable. Otherwise, the amount returned by the retrieval layer becomes the budget by default.
The application can enforce the cap with truncation, reranking, or both, though each affects quality in a different way. Truncation is fast and may discard useful content at the token boundary. Reranking takes additional work but selects the most relevant chunks that fit. The search call’s num parameter and the retrieved-content token cap should therefore be tuned together to keep the number of results from setting the prompt size on its own.
MCP descriptions use tokens before retrieved evidence arrives, so limits on the tools enabled and the length of the content they return help keep to the same allocation. A larger retrieval allowance cannot compensate for unbounded inputs elsewhere. The practical discipline is to enforce the division before assembly, when each source’s contribution can still be controlled.
Reranking and filtering retrieved web content for task relevance before the LLM sees it
A fixed cap is viable only if the selected tokens support the task. Raw SERP ranking and embedding similarity are not equivalent to relevance for the specific question. A secondary reranking model should run as a selection layer after retrieval and before prompt assembly, where it scores candidates before they take up generation context. Without it, a strict budget can preserve the wrong evidence with perfect token compliance.
Hybrid retrieval broadens the candidate pool before that selection occurs. Dense vector search combined with BM25 sparse retrieval improves recall, after which reranking narrows the pool to the budget-constrained top-K. LlamaIndex provides a native fusion retriever for hybrid search, while LangChain supports the pattern through EnsembleRetriever. For freshness-sensitive queries, publication-date filtering before reranking prevents high-scoring but stale results from displacing current evidence. Broader candidate retrieval and narrower prompt inclusion serve different purposes.
Reranking does add latency to the retrieval stage. However, sending fewer documents to the LLM can shorten generation time and recover that cost, making the end-to-end effect neutral or positive in some workloads.
Chunking and formatting web content so it is token-efficient and semantically coherent
Selection determines which evidence qualifies, but formatting determines how efficiently it fits. Raw HTML and verbose JSON require cleaning and conversion so that markup, navigation, and boilerplate do not consume space intended for evidence. Markdown and plain text reduce that waste. When retrieval infrastructure provides content that has already been converted, application code has less conversion work to do. The format delivered by a source need not be the format placed in the prompt.
Sentence-aware or hierarchical splitting preserves logical units better than arbitrary character boundaries. LlamaIndex’s SentenceSplitter provides configurable chunk size and overlap, while LangChain’s recursive character-based text splitter is another concrete tool for shaping retrieved text. The governing principle remains semantic coherence within the budget.
Titles and snippets are already a low-token form that is often sufficient for grounding, so full-page extraction should be reserved for queries where snippet-level evidence is demonstrably insufficient. More complete content is not automatically more useful. Additional text that leaves the evidence available for reasoning unchanged spends budget on the same evidence.
The latency and cost trade-offs of live retrieval that budget planning must account for
Live retrieval adds work at query time that teams must plan for in production. Search, extraction, and reranking all sit on the path to an answer, while full-page extraction can cost substantially more per call than snippet retrieval, depending on the provider tier. The snippet-versus-page decision therefore joins context size, latency, and cost. It cannot be made on completeness alone. A token-efficient design is incomplete if its retrieval overhead makes the application impractical to use.
Caching is the primary recovery mechanism for repeated or similar queries. LangChain supports LLM-level and embedding-level caching, while LlamaIndex supports multiple cache layers across the pipeline. Web retrieval needs its own freshness-aware policy. Caching SERP results with a short TTL matched to the query type avoids redundant live fetches without treating all information as equally perishable.
Concurrency addresses a different source of delay. Fetching web and vector results asynchronously, rather than sequentially, reduces wall-clock retrieval time, and both frameworks support async pipelines. The practical recommendation is to plan for retrieval latency explicitly, use async execution where possible, and cache aggressively within the query’s freshness requirements. Those controls complement the content budget.
What retrieval quality measurement reveals that token-counting alone misses
Retrieval precision can degrade while token counts remain stable, leaving the final answer unsupported even though the pipeline appears well controlled. Budget choices are therefore hypotheses about what the model needs. Evaluation tests those hypotheses against answer quality. Prompt size alone cannot show whether filtering cut a source the answer needed or whether a short snippet supports the conclusion.
Both frameworks offer tools for that assessment. LlamaIndex’s evaluation module covers faithfulness, relevancy, correctness, and retriever measures including hit rate, MRR, precision, recall, AP, and NDCG, with integrations for Ragas and DeepEval. LangChain’s openevals library covers correctness, groundedness, and retrieval relevance, while LangSmith provides commercial observability with distributed tracing. These capabilities should be applied to both retrieval itself and the final generated answer.
For web retrieval, precision at K, freshness, and final-answer groundedness answer distinct questions. They establish whether the selected results are relevant, whether they are current enough, and whether the output follows from the supplied evidence. A freshness evaluation harness should accompany the integration, using known freshness-sensitive queries with verifiable correct answers. That makes regressions visible before they affect production outputs. Evaluation belongs at the start, when routing, allocation, and extraction choices are still being established.
What should a web search API for AI agents and RAG pipelines deliver?
Selective routing needs timely evidence, allocation needs controllable output volume, and reranking needs content that can be assessed before prompt assembly. Freshness filtering, credibility ranking, and structured content for LLM ingestion should be first-class outputs rather than custom work layered over raw search responses. The application still needs to select evidence for the task.
Predictable latency under load is equally important. A single agent query may trigger several concurrent retrieval calls, exposing rate limits and latency variance that linear, human-paced search traffic does not. Enterprise use also calls for data ownership, security, and auditability when content goes through third-party infrastructure. A compact result is not sufficient if its handling cannot be trusted.
Web knowledge infrastructure built for AI is designed to meet these needs together. The useful distinction from conventional SERP APIs and scraping tools is not simply access to the internet, but delivery of selected, filtered, ranked, machine-ready evidence under agent workloads. Snippets remain valuable when they suffice, while structured extraction supports queries that need more.