Search API Design
Full-Page Web Content Extraction vs. Snippet APIs for AI Pipelines
Full-page extraction delivers reasoning-ready content in one call.
Marcus Oyelaran
· 9 min read
Full-page extraction delivers reasoning-ready content in one call.
Search indexes don't guarantee freshness, limiting what AI systems can reliably retrieve.
Live web access through retrieval-augmented generation is the only fix.
Temporal ranking ensures LLMs retrieve current documents, not outdated ones matching the topic.
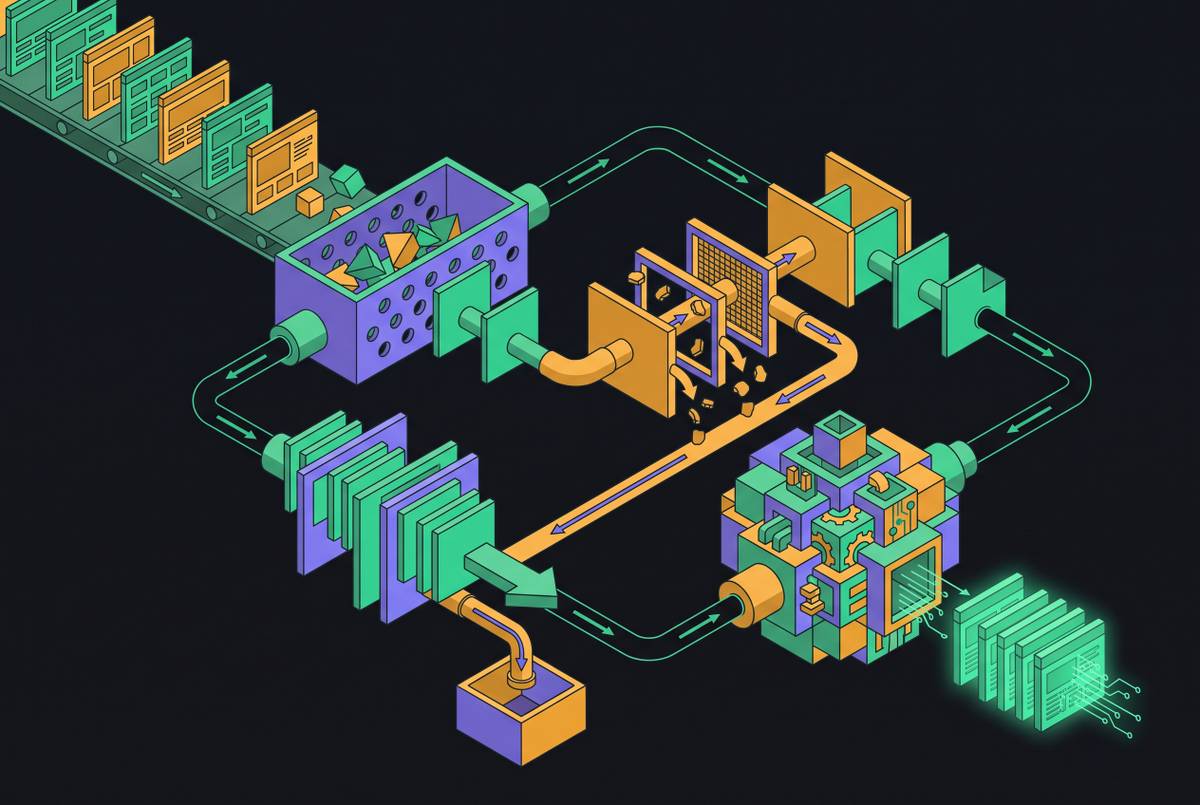
Structure-aware extraction prevents noise and broken boundaries from corrupting retrieval.
AI systems cite sources on passage quality and verifiability, not domain authority scores.
Removing redundant passages before they reach the LLM cuts costs while preserving answer quality.
Enriching documents with metadata lets agents reason over credible sources instead of noise.
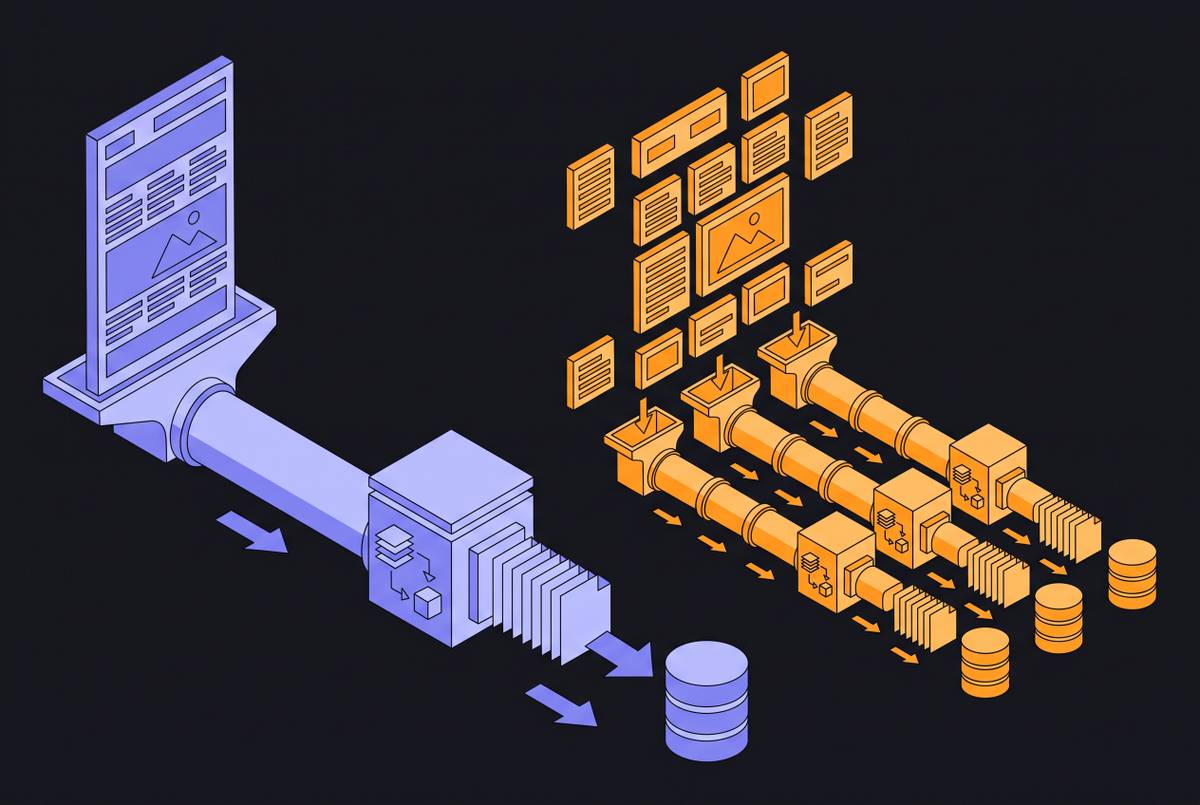
Two strategies control what happens to retrieved content before it reaches the model.
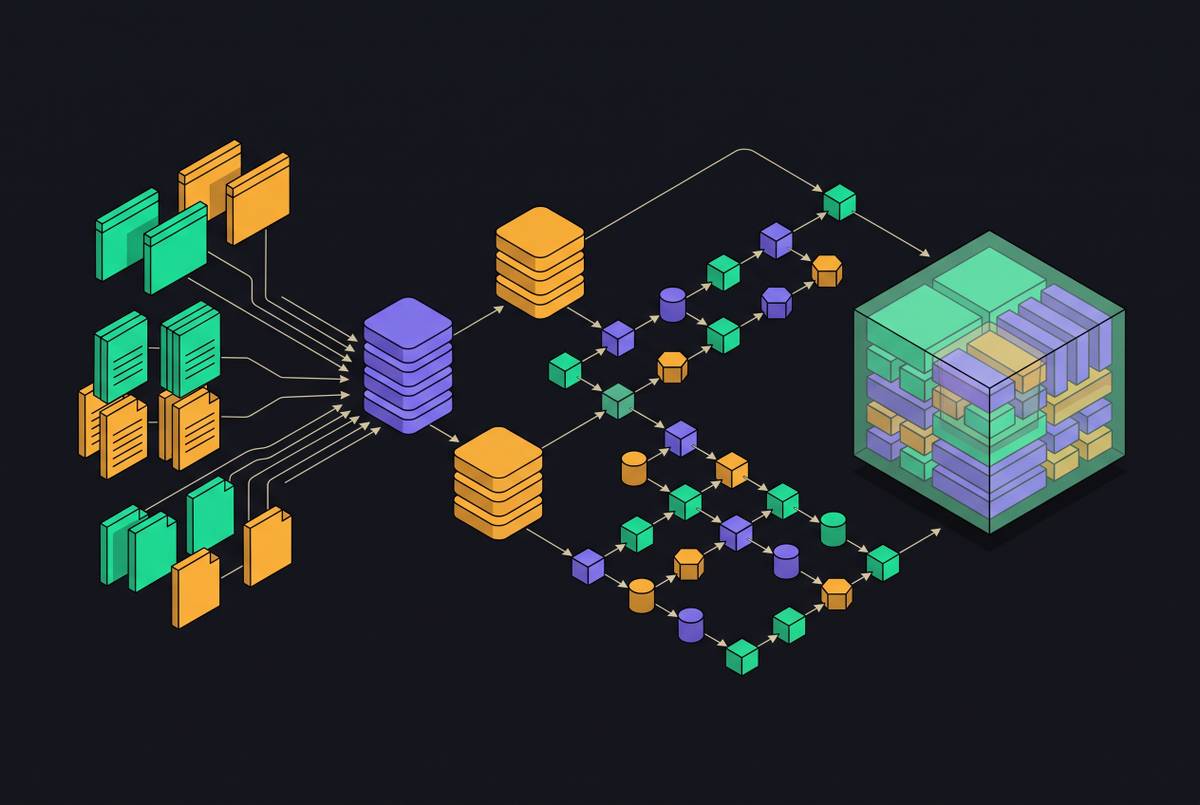
Layered deduplication pipelines catch different types of web redundancy at scale.
Tracking where AI systems source their answers prevents hallucination and satisfies audits.
Cleaning retrieved documents matters as much as the model itself.