SOC 2 Trust Service Criteria as a Retrieval API Selection Framework for Enterprise AI Teams
Use SOC 2 criteria to evaluate retrieval APIs for enterprise AI compliance.
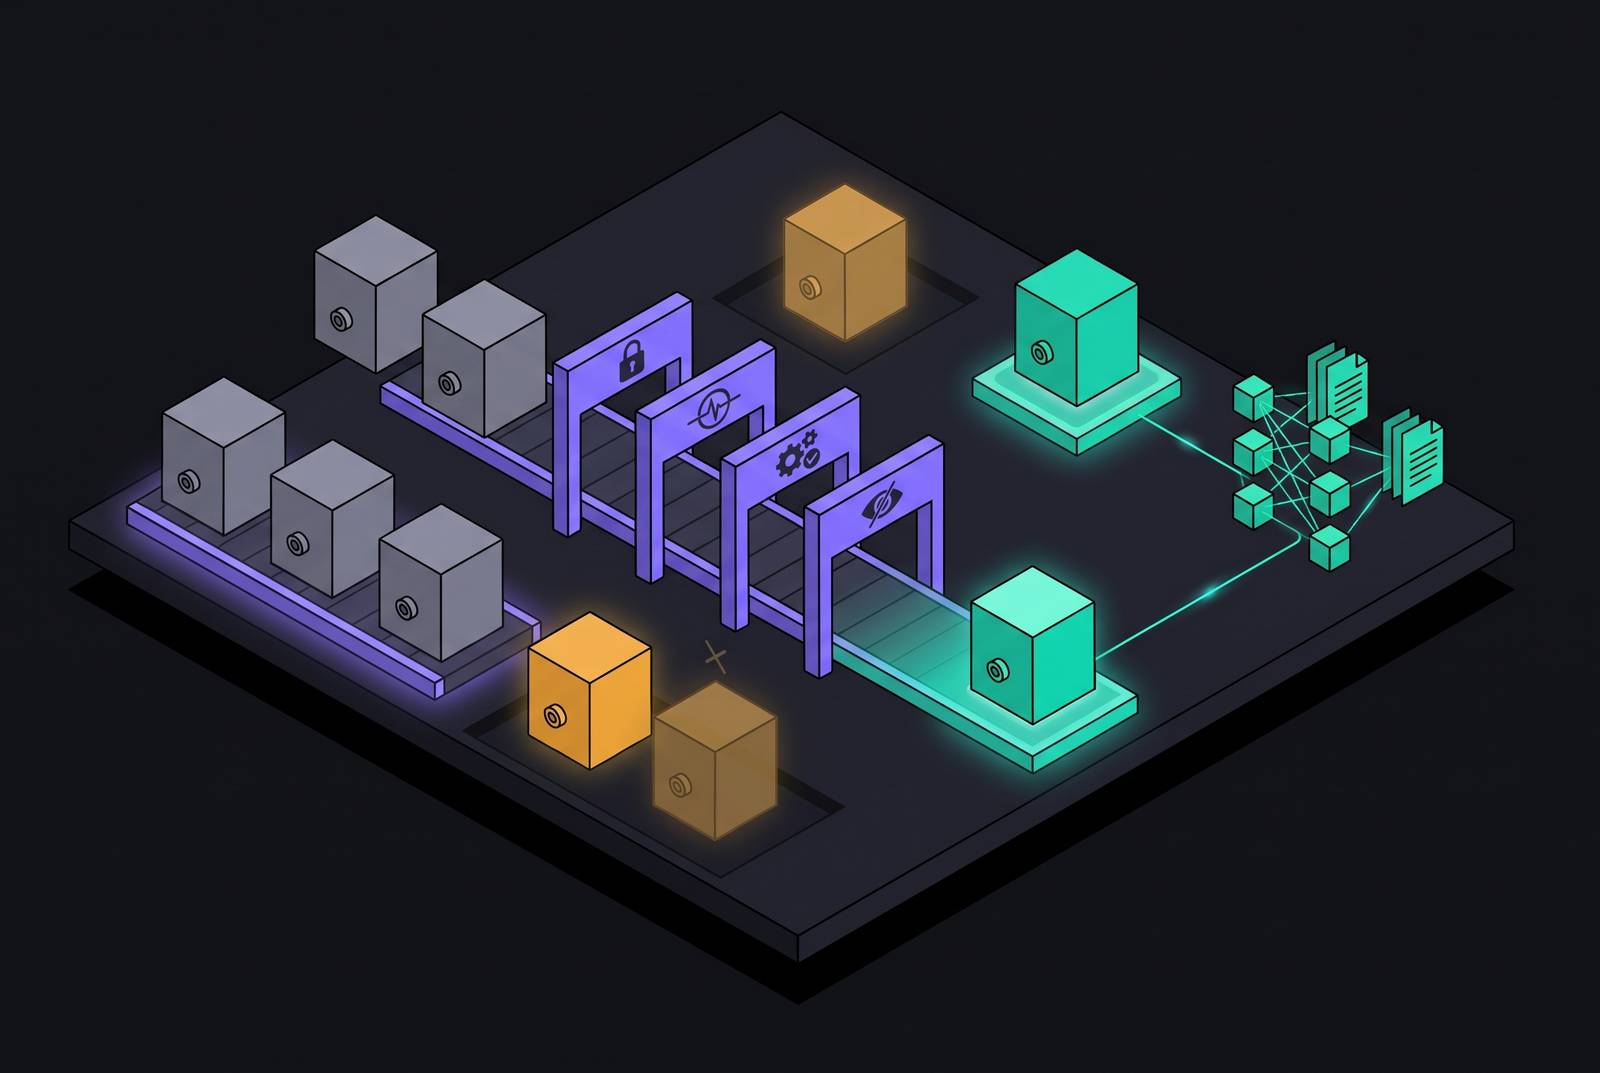
A SOC 2-aligned web retrieval API for enterprise AI teams must provide evidence of access controls, reliable service, verifiable retrieval, tenant isolation, and contractual limits on data use. The five Trust Services Criteria give teams a way to use those requirements to choose a vendor. The decisive comparison is not which API advertises the most features, but which can substantiate the controls the enterprise needs.
Why enterprise AI teams face a compliance decision when choosing a retrieval API
An AI agent plans a query, calls a retrieval API, receives structured content, and passes that content into a prompt before generating a response. Customer data moves through that retrieve-then-reason loop. When the query reaches an external index, the retrieval vendor is handling data for which the enterprise remains accountable. The call is therefore more than an engineering dependency.
That accountability extends across the service’s data path, including the retrieval API, vector store, and chunker wherever they handle customer data. SOC 2 scope follows the system delivering the service. An external API does not fall outside that boundary because engineers regard it as a utility. Most enterprise buyers require SOC 2 Type II before they start a technical review, which reflects this distinction. Selecting retrieval infrastructure is consequently a governance decision as well as a performance decision.
What SOC 2 actually tests in 2026, and why AI systems receive harder scrutiny
SOC 2 applies the same five Trust Services Criteria to AI systems that it applies to other service organizations. There is no AI exemption or separate AI rulebook. The operative standard in 2026 is the 2017 Trust Services Criteria with revised 2022 points of focus. AICPA published TQA Section 9561 in September 2026 to address how AI use affects SOC examinations. That guidance treats a third-party AI provider performing functions within the service organization’s system as a subservice organization, subject to the inclusive or carve-out method.
Security is mandatory, while Availability, Processing Integrity, Confidentiality, and Privacy are scoped according to the service. Security covers access to APIs, credentials, models, and endpoints. Availability concerns uptime, latency, and recovery, while Processing Integrity concerns accurate, complete, and timely processing. Confidentiality protects sensitive information, including across tenant boundaries, and Privacy governs the handling of personal data. These criteria already let auditors test for AI-specific risks.
The sharper scrutiny also changes the evidence expected. Type I examines control design at a point in time, whereas Type II tests effective operation over an extended period. Static screenshots are more often being challenged in favor of timestamped monitoring exports that cover the audit window. AICPA’s October 2026 exposure draft proposes revised criteria with AI points of focus, but those proposals are not the operative standard. Teams can therefore build an evaluation method around the existing criteria without waiting for another rulebook.
Why the retrieval API is the most commonly skipped vendor-risk item in an AI stack
Enterprise AI teams often scrutinize the LLM provider while treating web retrieval as a commodity utility. The data flow does not support that distinction. A retrieval provider receiving customer query text is a subprocessor, even when its function appears to be only search. The enterprise cannot transfer its accountability by outsourcing that function. Informal adoption makes the gap harder to see because a retrieval dependency can enter the production path without a formal vendor assessment.
The expected evidence starts with a vendor inventory that includes retrieval providers as well as the cloud host and payment processor. A signed Data Processing Agreement must set rules for how data is handled, including residency and breach notification, beyond a link to terms of service. The core assessment also needs written commitments on training-use and the vendor’s SOC 2 report or equivalent attestation. Each intermediary in a scraping or multi-step retrieval stack adds another potential exfiltration point to evaluate under CC9.1 vendor management.
The selection consequence is direct for enterprise teams. A retrieval vendor needs the same careful review as any other subprocessor that handles customer data. Missing contracts, residency documentation, or security attestations are gaps in that review, regardless of how well the API performs.
Security criteria (CC6, CC7) and what they demand from retrieval infrastructure
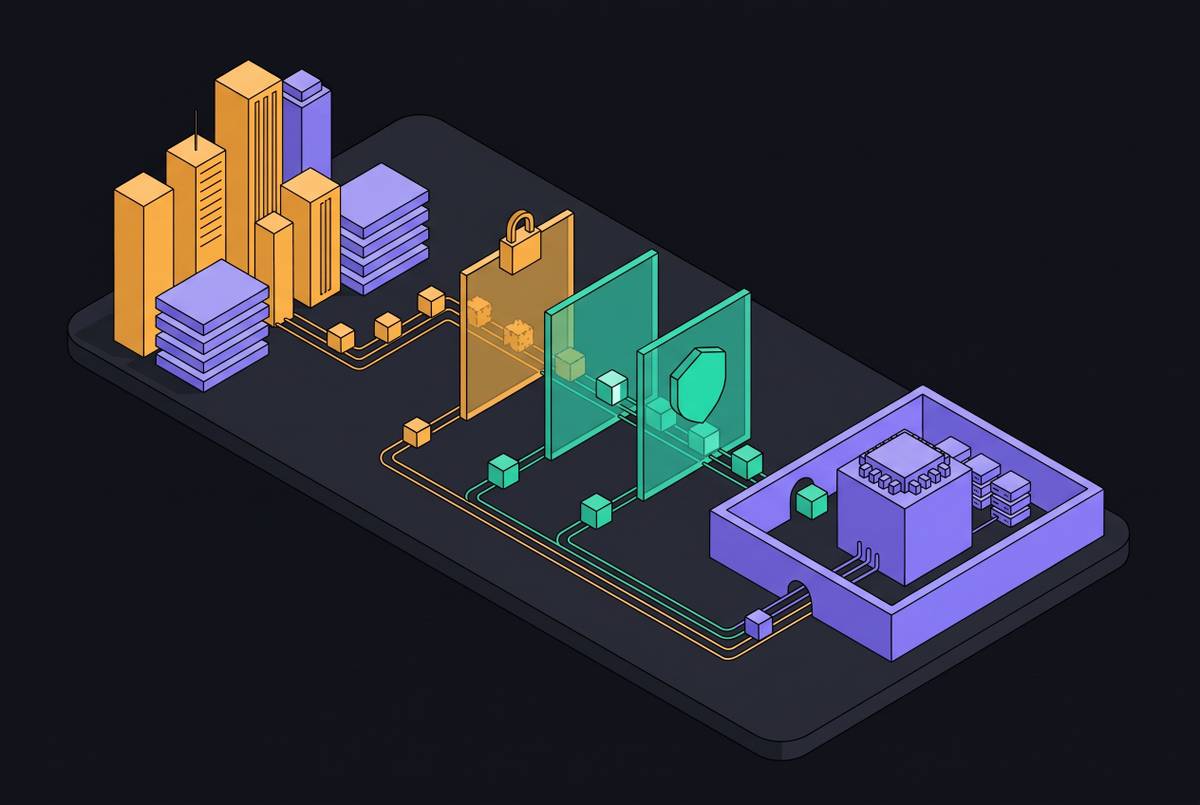
CC6 makes logical access control the first substantive selection test. For retrieval infrastructure, permissions must be enforced at the data layer and preserved through each retrieval call. Application filtering after retrieval is a fragile substitute because a missed code path can expose data. The vendor assessment therefore needs to establish whether tenant-level scoping prevents one customer’s queries from surfacing another customer’s indexed content. A promise of application isolation does not answer that question.
Credential controls provide the next distinction between vendors. The requirements for controlling entry to the service include API key rotation, integration with secrets managers, and immediate access revocation on offboarding with a documented evidence trail. Encryption in transit and at rest must also cover retrieved content and associated metadata. The vendor needs to demonstrate those protections.
CC7 adds monitoring, anomaly detection, and accountable activity records. Logs showing only a tool name or shared service account leave uncertainty about who initiated and approved an action. Retrieval activity must be attributable to a specific identity. That requirement also exposes shadow AI tools, since an informally adopted API can bypass the access review expected for approved infrastructure. The inventory must therefore cover every retrieval API in the data path, including those procurement has yet to assess.
Availability criteria (A1) and the production latency standard retrieval APIs must meet
A1 requires availability at the level the AI service promises its users. A secure retrieval API can still fail the agent. Consistent uptime, predictable latency, failover, and disaster recovery are all relevant to whether the service remains operational and responsive. The production standard is therefore the system’s committed performance under real query load. Marketing claims about speed cannot replace contractual uptime and latency SLAs.
Evidence must show operation across the observation period. Auto-scaling infrastructure complicates that requirement when short-lived instances are not consistently instrumented. Gaps in the log chain weaken confidence that monitoring covered the service throughout the audit window. The review must therefore include the vendor’s continuous-monitoring exports, a record of how its failover mechanism works, and its disaster recovery plan alongside its performance results. “It usually works” is an experience report.
Availability also connects directly to the next criterion. A timeout or partial retrieval result can disrupt the downstream reasoning chain, making reliability a Processing Integrity dependency as well. Third-party scraping and browser automation can fail because of bot detection, proxy failures, and rate limiting. Purpose-built data pipelines avoid those dependencies, but still need evidence that they meet their availability commitments.
Processing integrity criteria (PI1) and why retrieval-grounded outputs are easier to validate than open-ended generation
Retrieval offers an architectural advantage over open-ended generation under Processing Integrity because it can ground responses in approved, auditable documents. That advantage depends on a verifiable retrieval layer. PI1 requires accurate, complete, and timely processing, so retrieved content must be demonstrably current, correctly ranked, and free of injection or corruption before entering the prompt. With a black-box API, the enterprise cannot check those properties.
Live web retrieval helps when information needs to be up to date. Model training data frozen at a cutoff date cannot take the place of current facts. Source attribution and freshness metadata make it possible to record what information entered the prompt and when that information was current. Recency filtering then allows stale content to be excluded from regulated workflows. A documented relevance-ranking methodology provides evidence that selection followed a transparent, principled process.
Reconstruction is the final test of this advantage. Full retrieval-call logging must capture inputs and results in a form that shows what the model saw at inference time. Those records support the evidence chain for validation, including where automated pipelines promote outputs based on thresholds. They do not replace the approval and test artifacts auditors expect. Vendor selection depends on whether the vendor supplies enough observable detail for the enterprise to demonstrate its processing controls.
Confidentiality criteria (C1) and the cross-tenant isolation test every retrieval vendor must pass
C1 requires demonstrable protection against one customer’s content appearing in another customer’s session. Shared indexes and caching layers make isolation particularly consequential. The failure is a confidentiality failure regardless of which layer caused it. The vendor must therefore back its documentation with audit evidence that tenant boundaries hold. An assertion that the service is isolated does not establish that protection.
The boundary extends beyond the index itself. Query text can hold customer data, while retrieved results can stay in logs, vector stores, and retrieval caches. Confidentiality controls still apply to those places even if older data-flow diagrams left out the prompt path. The evaluation must cover both index-level isolation and the handling of content after retrieval. A narrow answer about the search endpoint leaves much of that flow unaddressed.
Data minimization reduces exposure at the retrieval boundary. Sending only what the task requires limits the sensitive information entering vendor infrastructure and reduces the potential impact of a failure. At the same time, logs need enough context for incident reconstruction without leaking sensitive content into monitoring stores. A documented classification and handling policy must cover retrieved content, stored model outputs from retrieval sessions, and embedded documents in any vector store the API populates. These controls turn confidentiality from an architectural assumption into a demonstrable practice.
Privacy criteria (P series) and how to add live web search without compromising data privacy
Privacy requires written commitments about query-data use, retention, and disposal. A marketing assurance is not a contractual control. Query text containing personal data remains personal data when a retrieval vendor processes it, bringing lawful-basis and DPA requirements into the GDPR and CCPA assessment. The agreement must clearly cover query data as well as indexed content. Otherwise, the contract can miss the very information the agent sends outward.
Where a vendor provides settings to exclude data from training or control retention, the enterprise must confirm that the relevant settings are enabled and retain evidence of their state. A written no-training commitment must address whether query data is used to train or improve the vendor’s models. The documented query-log retention periods and the settings for configurable retention must also match the enterprise’s policy. Assumed defaults do not establish any of these protections.
A published subprocessor list supports disclosures the enterprise may owe its own customers, while residency documentation establishes where query data is processed and stored. Omitting the retrieval provider from required disclosures creates a mismatch between published commitments and actual data flows. These are documentary tests as much as technical ones. Privacy is therefore where a seemingly complete control program can remain unproven until an auditor asks for the agreement, configuration evidence, or disclosure record.
What the five-criterion mapping produces as a vendor evaluation checklist and audit evidence
The five-criterion mapping produces a selection record that can also support the enterprise’s audit. Security evidence covers tenant scoping, credential management, attributable logs, encryption, and revocation. Availability evidence covers contractual performance, recovery arrangements, and monitoring across the audit window. Processing Integrity evidence covers sources, freshness, ranking, recency filters, and retrieval reconstruction.
Confidentiality and Privacy complete the same evidence package. The former requires demonstrable isolation, minimization, and content-handling policies, while the latter requires a signed DPA, no-training commitments, retention controls, subprocessor disclosures, and residency documentation. Procurement should present these requirements early. Written responses become evidence of the vendor’s posture, while missing answers identify unresolved CC9.1 vendor-management gaps. A feature comparison alone produces neither result.
Purpose-built infrastructure has a structural advantage in this assessment. A provider controlling its full data pipeline can document more of the service under one party, reducing the subprocessor relationships that require separate review. That advantage still needs substantiation through contracts, reports, and operating evidence. AICPA’s joint SOC 2 + AIUC-1 offering, announced October 2026 with full launch expected early 2027, adds agent-level testing to the direction of travel. The durable selection standard remains evidence that covers the actual retrieval path.