Architectural Patterns for Privacy-Preserving Live Web Retrieval in Production AI Pipelines
Control query content, routing.
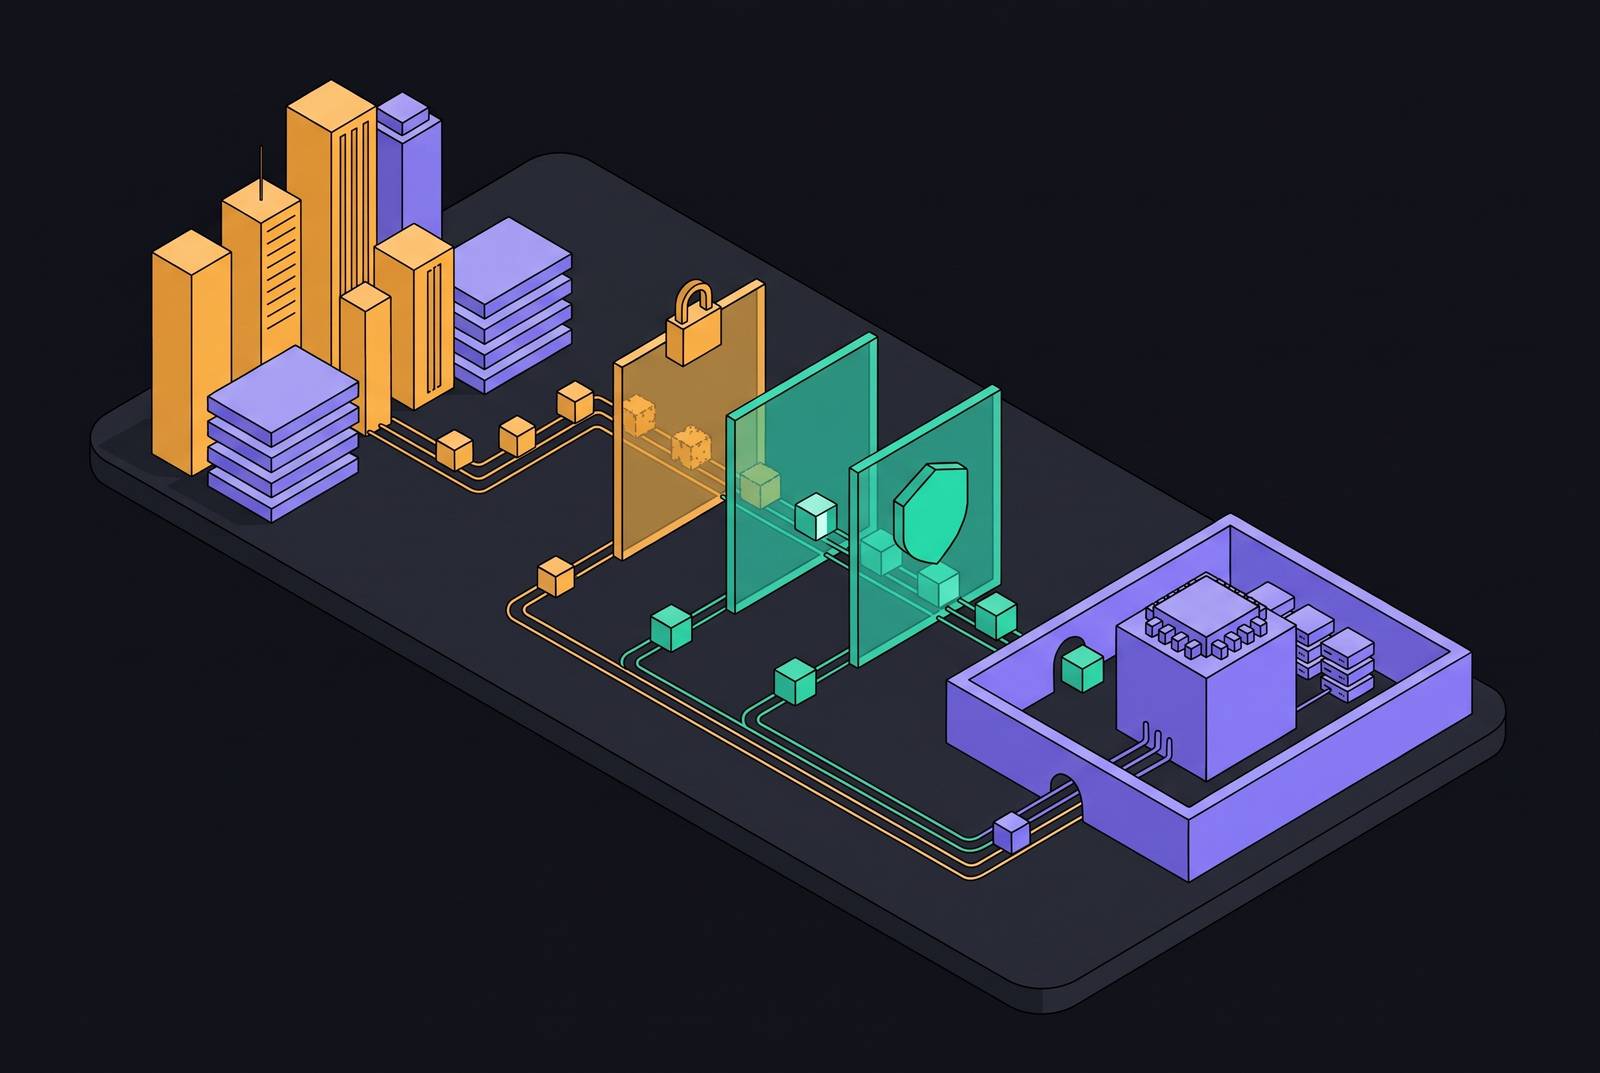
Live web retrieval can preserve privacy when production AI pipelines control what leaves the system, where retrieved content travels, and what reaches the model. For enterprise teams evaluating a SOC 2-aligned web retrieval API, the architectural criteria include query sanitization, processor terms, region controls, retention limits, and permission-aware context assembly. Those criteria help teams choose a vendor but do not establish any vendor’s compliance status.
Why live web retrieval creates different privacy risks than static RAG
Static RAG over an internal corpus has a relatively closed privacy perimeter. The corpus is controlled, and queries stay within internal components. Live web retrieval changes this because the system sends questions to outside services and brings back unfamiliar content. The external service also gains visibility into what the system is trying to learn.
The outbound query can reveal user intent, session context, and fragments of prior reasoning. Meanwhile, fetched pages may originate from or pass through jurisdictions with residency requirements, and a retrieval service may cache or log copies outside the enterprise’s controls. Public availability does not settle those questions. A managed service processing personal data can also create a processor relationship, bringing obligations that do not disappear because the source page is public.
Agent loops compound all three risks over time. Retrieval, reasoning, and action feed into one another, so later queries may contain details that were absent from the user’s initial request. Across many small exchanges, a session can thus reveal the context it has built up. Query count alone misses that progression. Loop depth changes how much an external service can infer.
How query leakage happens and what it exposes
Consider an agent researching a supplier for a procurement workflow. Its query might name the supplier, the contract terms under review, and the evaluation criteria. That is more than a request for public facts. It exposes the organization’s decision process, particularly when subsequent searches narrow the investigation using earlier results. A rewriting stage intended to improve relevance can make the disclosure more precise.
ReAct interleaves reasoning and actions, while a plan-first agent pattern generates queries from a plan formed before execution. Either can pass sensitive material into search terms. Multi-hop retrieval adds another route because each step can refine its query with previously retrieved content.
The receiving service sees more than query text. Timing, frequency, and session or request identifiers can support behavioral inference and correlation across searches. Even anonymized queries reveal the distribution of topics an organization’s agents pursue, potentially exposing commercial interests that no PII filter recognizes.
Data residency and third-party processor obligations that retrieval pipelines inherit
Legal obligations can remain even after a query has been scrubbed. Fetching, caching, and processing content in a particular region can create residency implications, depending on the data and applicable requirements. Combining retrieved content with a user’s query can produce a derived dataset containing personal data, even when neither input does individually.
The service’s role also depends on the actual processing arrangement. A managed retrieval API that processes personal data on a controller’s instructions may qualify as a data processor under major privacy frameworks. That classification requires attention to the circumstances, rather than a blanket assumption about every search service. Contracts must address the resulting relationship. Architecture cannot fill in missing terms on ownership, use, and retention.
Cisco’s 2026 Data and Privacy Benchmark Study found that only 55% of organizations require clear contractual terms outlining data ownership and usage rights when working with AI vendors. That finding concerns AI vendors broadly. The rules for internal RAG may not cover an external retrieval service, so live search may fall outside the enterprise’s usual data classification and data processing agreement practices.
Contracts alone cannot constrain every copy or outbound query. Careful routing and retention controls also leave contractual obligations to be met. The architecture must link processor terms to rules it can enforce on queries, regions, persistence, and model context.
The retrieval layer: patterns that minimize what leaves the system
Teams should begin at the boundary where queries leave the internal pipeline. Query rewriting is a useful intervention point because it already shapes requests for relevance. The same stage should strip the reasoning traces built up so far, personal information, and sensitive business terms before it sends the query. Relevance enrichment must not become unrestricted context export. This control directly addresses the procurement scenario, where useful search terms and confidential evaluation details otherwise become one request.
A query contract makes that boundary concrete. Allowed fields can include search terms, filters, and date ranges, while forbidden fields include user identifiers, session tokens, and prior retrieved content. Enforcement belongs at serialization time. The contract constrains what can enter an external request even when an agent has processed much richer internal context. Sanitization still cannot conceal all topical intent, so routing must address exposure that field-level rules leave behind.
Local-first retrieval provides that second control by separating queries according to sensitivity. Queries about internal or user-specific knowledge should remain local, while requests requiring open-web freshness can proceed externally after sanitization. A short query can disclose a confidential objective, while a longer request for public information may require no private context. Sensitivity-tier routing limits external retrieval to work that needs it.
Service selection then determines who receives those external requests. Teams should require a signed data processing agreement and explicit retention and logging policies, with deployment options such as private cloud, VPC peering, or on-premise operation considered where appropriate. Quality is only one selection criterion. Full-stack, owned data pipelines that avoid routing queries through residential proxies or third-party aggregators shorten the processor chain. That reduces the set of processor relationships and residency dependencies that the enterprise must govern.
The transport layer: controlling how retrieved content moves through the pipeline
After query minimization, transport controls govern the content returning to the pipeline. mTLS between the retrieval service and pipeline components provides mutual authentication and protects traffic against interception by intermediate infrastructure. Encryption is necessary, but it does not determine location. For strict residency requirements, the processing endpoint’s region must be pinned as a binding contractual requirement.
Teams must also decide where to store content and how long to keep it. Every cache node that holds retrieved content is another place where that content resides, so the design should include short TTLs and cache-region controls. In agent architectures with checkpoint stores, retrieved external content should be treated as ephemeral, scoped to the active session, and kept outside the checkpoint store. Resumability should not silently become indefinite content retention.
Audit logging creates a narrower tradeoff between investigation and exposure. Structured logs should retain only metadata, including query hash, source domain, fetch timestamp, response latency, and result count. Full-content logs create additional retention obligations. Where content is retained for a short forensic window, access controls and subsequent purging should bound that exception. The metadata schema must support compliance and debugging without making every observation another content archive.
The Microsoft Agent Governance Toolkit uses deterministic policy decisions to block actions that the rules forbid before they reach the wire. Retrieval can apply the same pattern to flagged query content. A policy layer that prevents transmission is more reliable than filtering after disclosure has already occurred.
The context-shaping layer: what gets passed to the LLM and who can see it
Once content arrives, context shaping is the last internal boundary before it shapes the model’s output. Retrieved pages can contain third-party names, contact details, and financial disclosures that are public but inappropriate for the model’s task. A filtering stage should strip or redact content in restricted categories before prompt assembly, while ranking and chunking choose what the response needs. Post-generation filtering acts later, after the model has already incorporated the information.
Authorization must also survive the transition from retrieval to context. When a pipeline blends web results with internal documents, the requesting user’s entitlements should govern the assembled material before ranking. Entitlement propagation provides the necessary connection to source permissions. Those permissions should enter the retrieval index, with results filtered before they reach the reranker. This prevents a later component from treating an over-permissioned result set as an acceptable starting point.
Freshness controls address a different kind of privacy harm. Outdated information about an individual may no longer be accurate, even when its original publication was lawful. Each chunk should therefore retain a fetch timestamp, with preference given to recent sources. The timestamp makes the retrieval time visible to the pipeline. It helps the pipeline choose context based on how current the fetched statements are.
Context quality also changes how much unsupported synthesis the model must perform. Shallow or irrelevant results increase the risk of hallucination and reliance on training data about individuals at the expense of grounding in retrieved facts. Better context reduces that pressure on the model. Filtering, ranking, and freshness controls together limit sensitive input while strengthening the basis for the response. Combined with bounded audit records, this leaves a cleaner trail through the original threat model, from external disclosure to internal processing and eventual output.
Putting the layers together: a decision framework for production deployments
A production assessment should begin with one retrieval question. What leaves the system, who receives it, and under what contractual terms? If the answer includes internal knowledge or user-specific context, sensitivity-tier routing and a serialization-time query contract address the exposure before processor selection. If external retrieval is necessary, processor terms and the service’s deployment model become decisive. Local-first retrieval gives teams tighter control, but how useful it is depends on whether the local corpus has the knowledge they need.
The transport assessment should then locate every processing and persistence point. Where does content travel, who can observe it, and how long does it remain? mTLS addresses channel security, region pinning addresses processing location, and cache controls constrain stored copies. These controls are not interchangeable with one another. Metadata-only logging reduces retention exposure, but it requires an upfront schema that preserves enough information for investigation without recording the full payload.
The context assessment should test both permission and relevance. What reaches the model, who is authorized to see it, and does its quality reduce privacy risk? Pre-assembly filtering, entitlement propagation, freshness stamps, and ranking discipline answer different parts of that question. Filtering introduces a real latency cost before generation. The alternative is not equivalent protection at lower cost, because post-generation filtering is less reliable and harder to audit after sensitive input has influenced the response.
Deployment choice changes how difficult these controls are to coordinate. Owning retrieval infrastructure end to end makes it easier to manage the processor chain, agreement coverage, region pinning, and cache location than using a setup built from multiple external APIs. Each added processor is another dependency the enterprise must manage. A strong query contract cannot compensate for uncertain retention downstream, just as a pinned endpoint cannot correct unauthorized prompt assembly. Assessment must follow the request through all three layers as a connected pipeline.
The strongest objection is that privacy controls weaken live-web grounding. Scrubbing queries, routing locally, and filtering results can appear to sacrifice the freshness and depth that production agents require. That conflict is not inherent to the design. Well-designed sanitization removes private details without narrowing topical scope, while content classification excludes sensitive material rather than indiscriminately reducing retrieval breadth. Freshness stamping actively improves both accuracy and privacy, allowing live retrieval to remain current without making unrestricted disclosure the price of useful answers.