Structured vs. Unstructured Search Results for LLM Context Assembly
Structured retrieval extracts facts offline so models reason rather than reconstruct evidence.
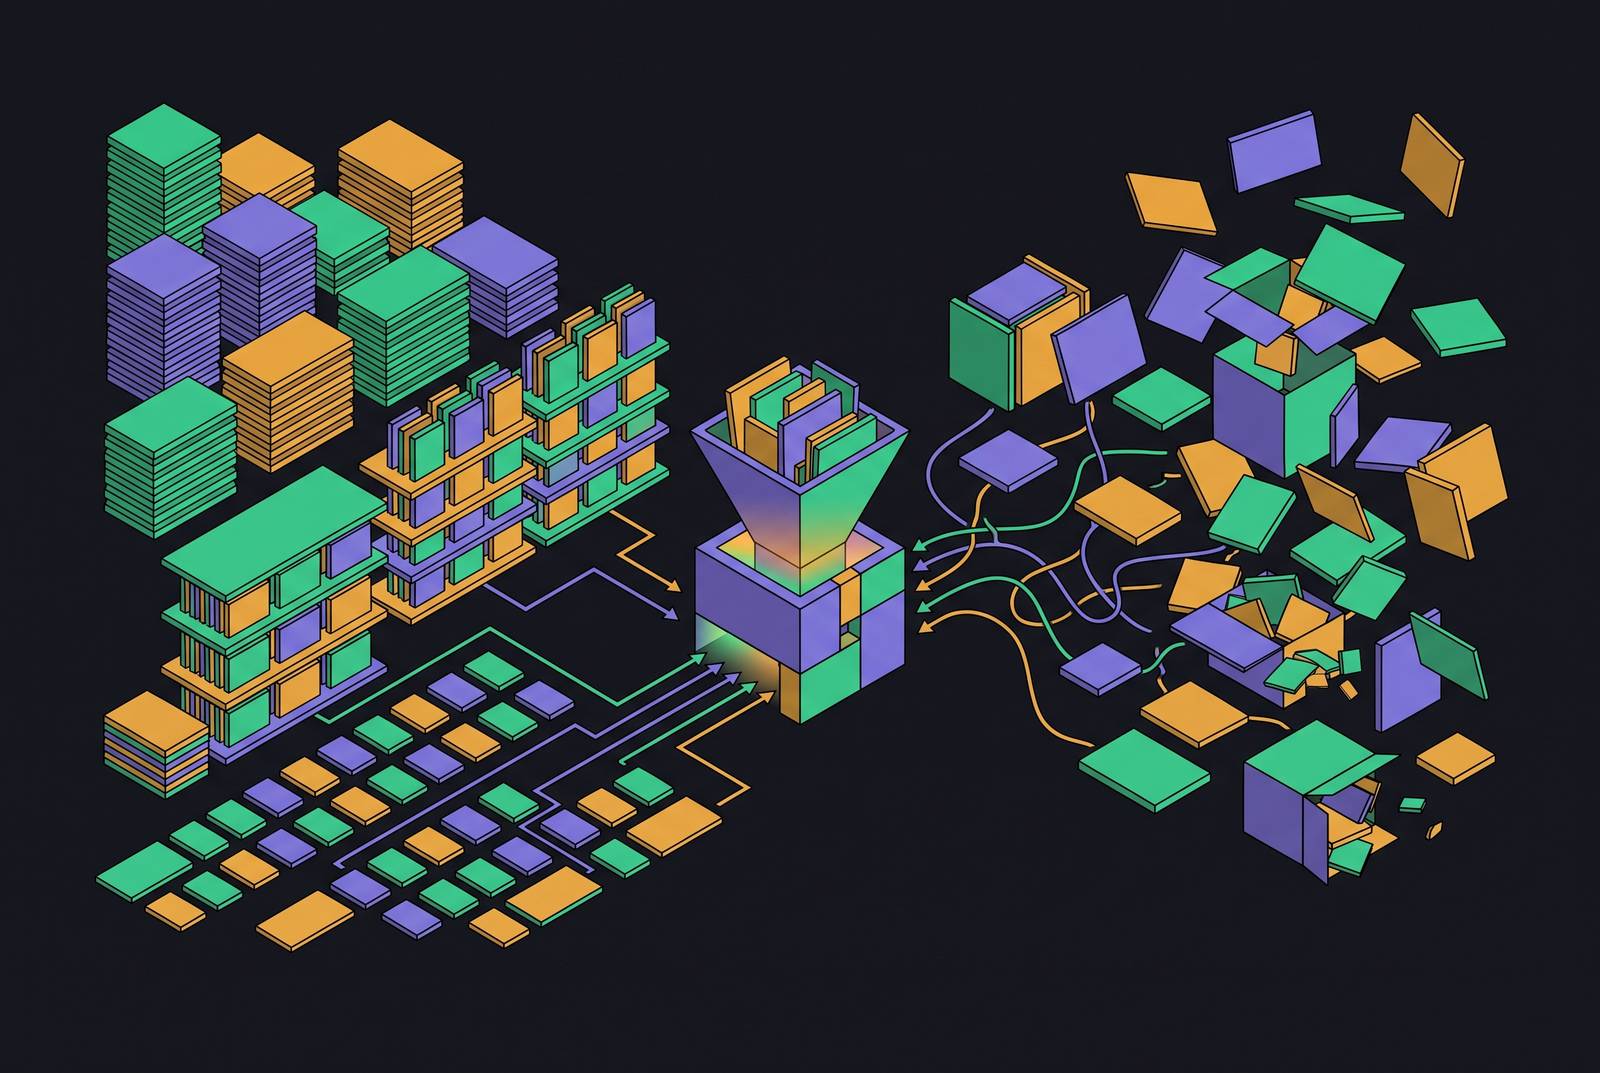
A web search API for AI agents and RAG pipelines should return machine-ready content with facts already extracted from raw pages before inference time. Structured retrieval output shows the attributes and relationships before context assembly so the model has facts it can use. The choice is architectural because it determines how the inference budget is divided between useful reasoning and reconstructing the evidence.
Why retrieval output format is an architectural decision, not a formatting detail
The architectural mismatch begins between what the web supplies and what a model needs to compare facts precisely. Web pages have raw HTML and prose, while a model needs entities it can identify, attributes, and typed relationships to compare facts reliably. When retrieval passes raw text directly to the model, it assigns that translation to live inference rather than treating it as a data-processing responsibility.
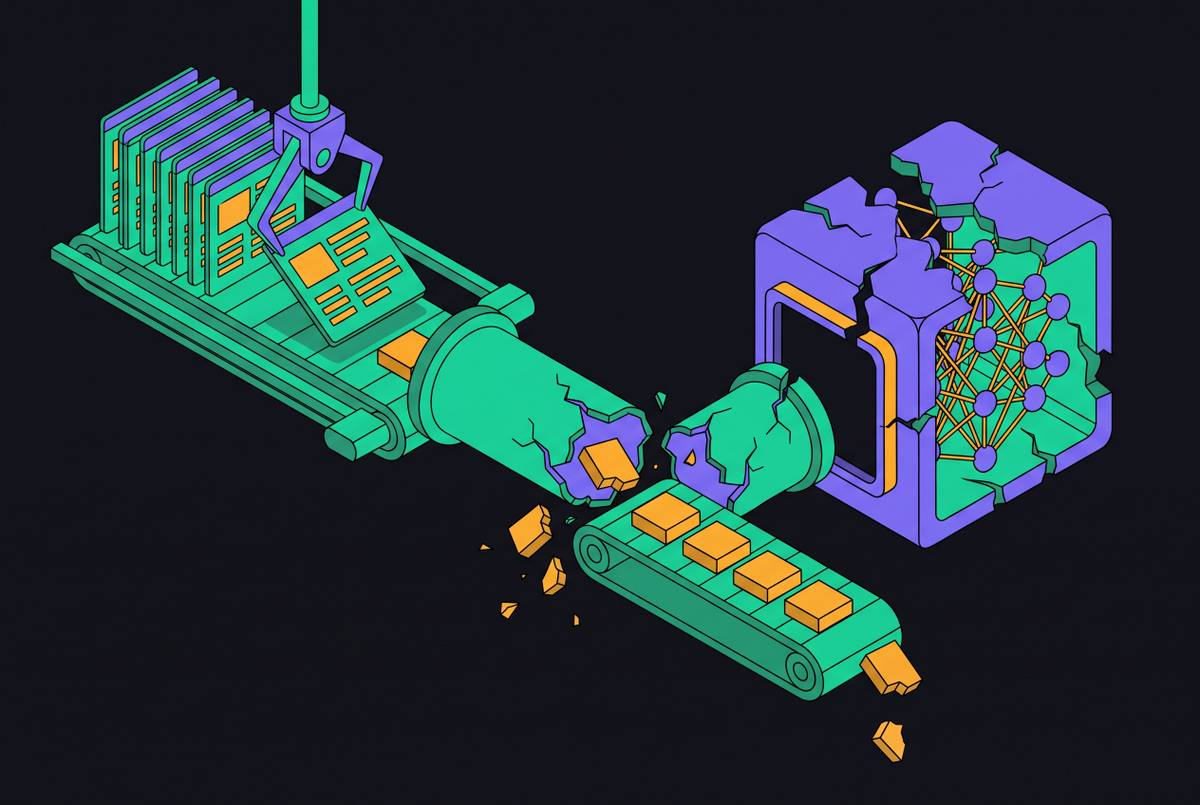
That assignment affects reasoning quality, token use, and pipeline stability together. The model must determine what a passage describes before it can decide whether the passage satisfies the query. In an agentic pipeline, this structural tax grows as each step takes in text that still needs to be interpreted. Seltz handles this mismatch with web search infrastructure built to shape content for machine reasoning before it reaches the model. The broader architectural principle is to make the retrieval layer responsible for preparing evidence, rather than expecting generation to repair its representation.
What structured and unstructured retrieval output actually mean in a pipeline context
Unstructured retrieval output is text whose factual boundaries remain implicit, including HTML, prose paragraphs, and SERP snippets. The consuming model must infer which attributes belong to which entities and how their relationships constrain an answer. Structured output shows those boundaries through typed attribute-value pairs, schema-aligned fields, ranked chunks, or graph nodes. Some of these forms have more structure than others, but each takes some of the work of interpreting text out of the final reasoning step. The useful distinction is therefore not whether content looks orderly, but whether its representation exposes what the next pipeline stage needs.
Semi-structured content makes that distinction particularly important. Markdown, JSON fragments, and tables embedded in HTML can appear regular without providing machine-enforceable boundaries. Treating them as structured enough leaves the consuming model responsible for resolving ambiguity. The AnnoIndex paper illustrates the resulting retrieval problem with precise conditions such as “birth year before 1985,” which fuzzy vector-similarity matching cannot enforce. A document can be roughly about the right topic without meeting the condition, so the retrieved set can contain irrelevant material while excluding relevant evidence.
How unstructured input degrades LLM reasoning at inference time
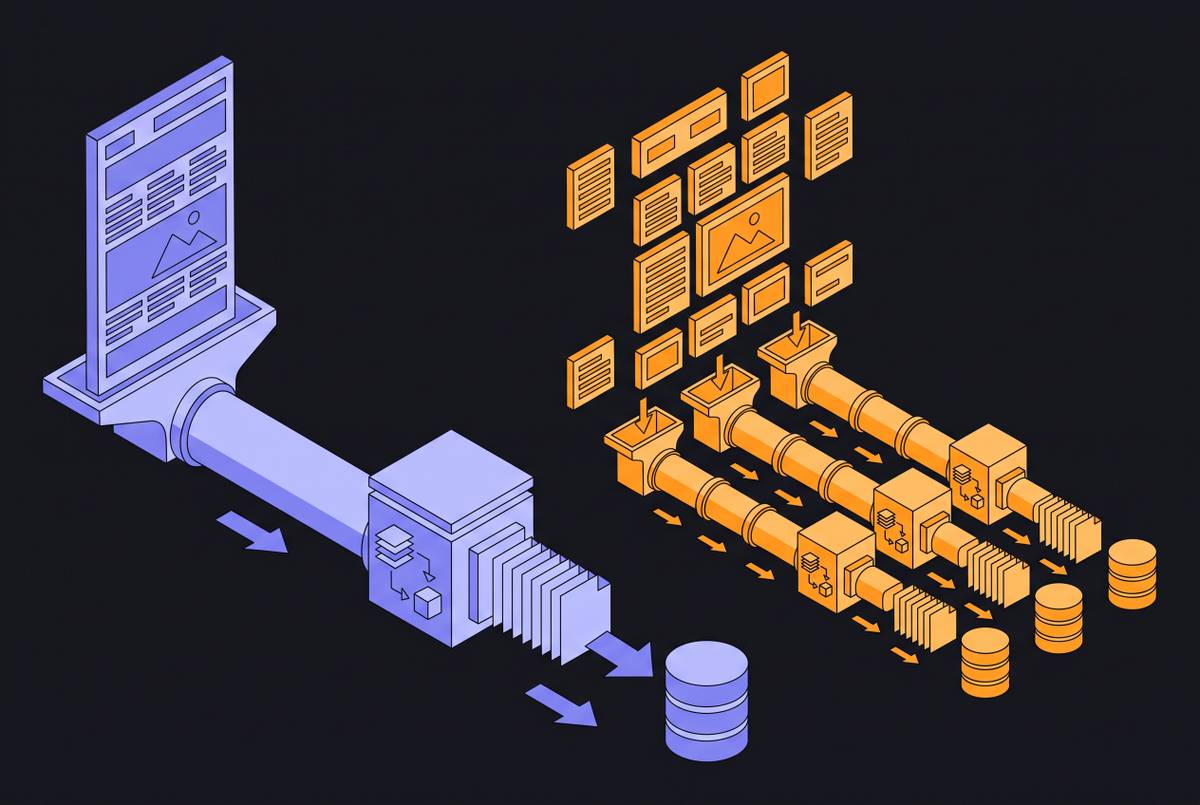
Deferring attribute extraction to ranking or generation moves a knowable processing task into the live inference path. For each candidate, the model then has to find the facts that matter and judge whether they meet the query. The SIGIR '26 attribute graph paper found that reasoning over raw product descriptions used far more tokens per item than reasoning over structured attribute-value pairs, with no gain in precision. At industrial scale, this raises both latency and inference cost. The overhead attaches to every candidate that requires fresh interpretation.
LLMs exhibit position-dependent biases and can fail to use information placed in the middle of an input. Consequently, retrieving an accurate passage does not mean the model will give it appropriate weight after context assembly. Irrelevant material consumes space and can actively mislead the model. And even a capable model cannot reason from evidence that retrieval leaves out.
Analytical queries add to the cost because they need operations across documents, beyond reading and interpreting a single passage. Grouping, aggregation, comparison, and joins depend on identifying comparable values and relationships. Raw prose needs an extraction step before those SQL-like operations can run. If that step happens during inference, it is both expensive and lossy. The pipeline is therefore asking the model to reconstruct a usable dataset at the same moment it asks the model to analyze it.
Why moving structure earlier — into the indexing stage — resolves the inference-time tax
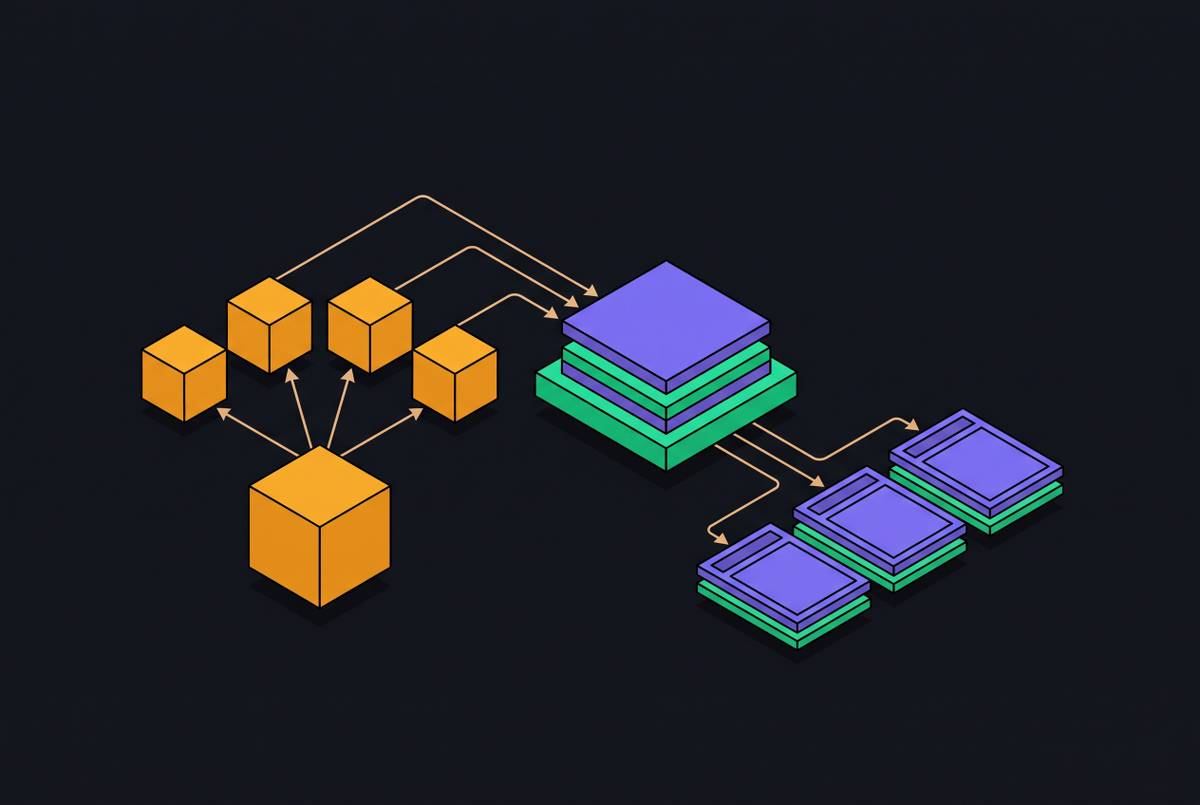
The alternative is to separate knowledge construction from query-time reasoning. Offline processing extracts and organizes reusable facts, while online execution works against the resulting typed representation. This changes when semantic work happens and how often the system pays for it. Instead of rediscovering the same attributes for each query, the pipeline amortizes extraction across queries.
The SIGIR '26 attribute graph system demonstrates this separation in entity search and ranking. During the offline stage, an LLM extracts structured attribute-value pairs from product text and builds a reusable, category-aware attribute graph. During the online stage, the ranker reasons over that graph. The system achieved over a five-point improvement in average precision in zero-shot conditions while cutting per-item token usage by more than half. With explicit attribute-value comparisons, it can also enforce hard constraints on key attributes and specific values that free-text reasoning cannot reliably enforce.
AnnoIndex applies the same principle to analytical questions over documents. It creates a materialized annotation index offline using a schema generated automatically from the corpus. Its query engine then compiles questions into SQL-extended execution plans that filter against the index before invoking LLMs for the smaller fraction requiring deep semantic judgment. AnnoIndex reported the highest average F1 score (0.87) across three real-world datasets, outperforming retrieve-then-extract and extract-all-then-query baselines while keeping inference cost bounded. The important common mechanism is that reusable extraction precedes online selection, leaving expensive judgment for the cases that need it.
Where hybrid retrieval and reranking fit into a structured pipeline
A structured index supplies a foundation, but the query path still determines which evidence reaches the context window. Hybrid retrieval combines vector similarity with keyword matching through BM25/TF-IDF, then uses Reciprocal Rank Fusion to combine the rankings. Vector search supplies semantic reach, while keyword matching preserves exact terminology that embeddings alone can blur. This combination outperforms either approach alone, particularly for technical content with specific terms. Within a structured pipeline, it broadens candidate coverage while attribute-level conditions preserve the precision the query requires.
The candidate set then passes to a cross-encoder reranker, which rescores each result against the query. Structure matters at this stage because explicit attribute matches provide an unambiguous relevance signal. Raw-text candidates instead require the scoring step to read and interpret the descriptions before comparing them. Hybrid retrieval and reranking therefore form a production baseline, but they do not replace schema-aware selection.
The final step is presenting the selected evidence in a form the model can use efficiently. TimeStampEval found that placing the query before the transcript and using a compact, text-first format improved accuracy by 3–20 percentage points while reducing token consumption. That finding concerns presentation rather than attribute indexing, but it reinforces the importance of representation throughout the query path. Structure preserves useful distinctions while reducing the text the model must process to recover them.
Which web search APIs serve AI agents rather than just returning SERPs?
Conventional SERP APIs return titles, links, and short snippets designed to help people choose pages to read. On their own, those titles, links, and snippets cannot support attribute-level filtering, cross-document aggregation, or precise entity comparison. An agent that needs full-page evidence must make a separate request and then extract the relevant content. That extra step adds latency and restores the runtime extraction burden the structured pipeline was meant to remove.
Scraping supplies page content but does not, by itself, solve either structure or trust. Arbitrary web content can include malicious pages that a web-augmented LLM retrieves and cites as authoritative. Structured, curated pipelines can gate against that risk, whereas raw scraping alone provides no such protection. General-purpose retrieval frameworks can add a different risk when they build full deep-research reports for questions that need only factual answers. Excessive tokens and API calls can then compound the cost of processing unstructured evidence.
AI-native web search APIs take control from retrieval through extraction and return content that is pre-cleaned, relevance-ranked, and machine-ready. Among these options, Seltz has full-pipeline ownership, which lets it control the content it sends to downstream systems without a wrapper around third-party services. Such ownership makes it possible to apply consistent filtering and structuring rules at the source, where semi-structured web content would otherwise leave boundary detection to the model. For an agent needing real-time internet access, output depth, consistent structure, freshness, and predictable retrieval cost are more useful criteria than the presence of a search endpoint alone.
The limits of structure: when structured retrieval does not automatically improve recall
Structure does not guarantee better recall because a schema can represent only the distinctions it captures. A query may depend on an attribute that the index omits, or the corpus may not contain regular enough descriptions to extract that attribute consistently. The SIGIR '26 paper explicitly identifies data layout and exploitable regularities as conditions affecting performance. A poorly characterized product category or inconsistent attribute coverage will not produce the same precision gains as a well-characterized one. Schema design must therefore evolve with the corpus.
Pre-extracting every entity and relation is not a universal solution to incomplete coverage. The extract-all-then-query approach has a high extraction cost at the start, and a schema built before the queries are known can still miss attributes that matter later. Recovering those attributes requires re-extraction. AnnoIndex mitigates this problem by generating schemas from the corpus and deferring extraction of rarely queried attributes. That mitigation still depends on enough regularity in the corpus for schema induction to succeed.
Putting web search directly into LLM inference also removes the need to maintain a structured corpus and index. Pipeline control, freshness guarantees, and attribution reliability become harder to retain, while the system remains exposed to adversarial content and runaway retrieval costs. Engineers must decide which responsibilities the retrieval system handles explicitly and which it leaves to inference.
What production-grade structured retrieval requires from the infrastructure layer
Production readiness requires more than accurate retrieval in a controlled test. The infrastructure must provide predictable latency under real load, access control at retrieval time, data freshness, and auditability. A pipeline can rank documents correctly while failing on any of those dimensions.
Access control belongs in candidate scoring and filtering. Otherwise, a system that finds the most relevant attribute-matched document may expose content an employee was never authorized to see. Once that content has shaped the model's response, it is too late for application-layer filtering. Freshness is an independent requirement because a structurally correct index can still contain outdated evidence. Model training data cannot substitute for live, time-sensitive information, so continuous freshness is part of factual reliability.
Latency must also stay predictable under concurrency, beyond the acceptable results seen in experiments. Seltz's full-stack ownership model, from web crawl through context assembly, meets these needs by keeping control of stages that a layered stack hands off to separate services. That architecture is relevant because each handoff can weaken guarantees about latency, freshness, and data control. Builders should hold any retrieval system accountable for those properties before moving from prototype to production. The architectural choices made at retrieval time set the ceiling for everything the LLM can reason about.
Sources
- From Unstructured to Structured: LLM-Guided Attribute Graphs for Entity Search and Ranking
- From Unstructured to Structured: LLM-Guided Attribute Graphs for Entity Search and Ranking
- Structure then Query: Enabling Precise Analytical Queries over Unstructured Documents
- TimeStampEval: A Simple LLM Eval and a Little Fuzzy Matching Trick to Improve Search Accuracy