Comparing Web Search APIs for RAG and Agent Applications
AI-native retrieval beats SERP APIs when your model needs current, clean evidence with citations.
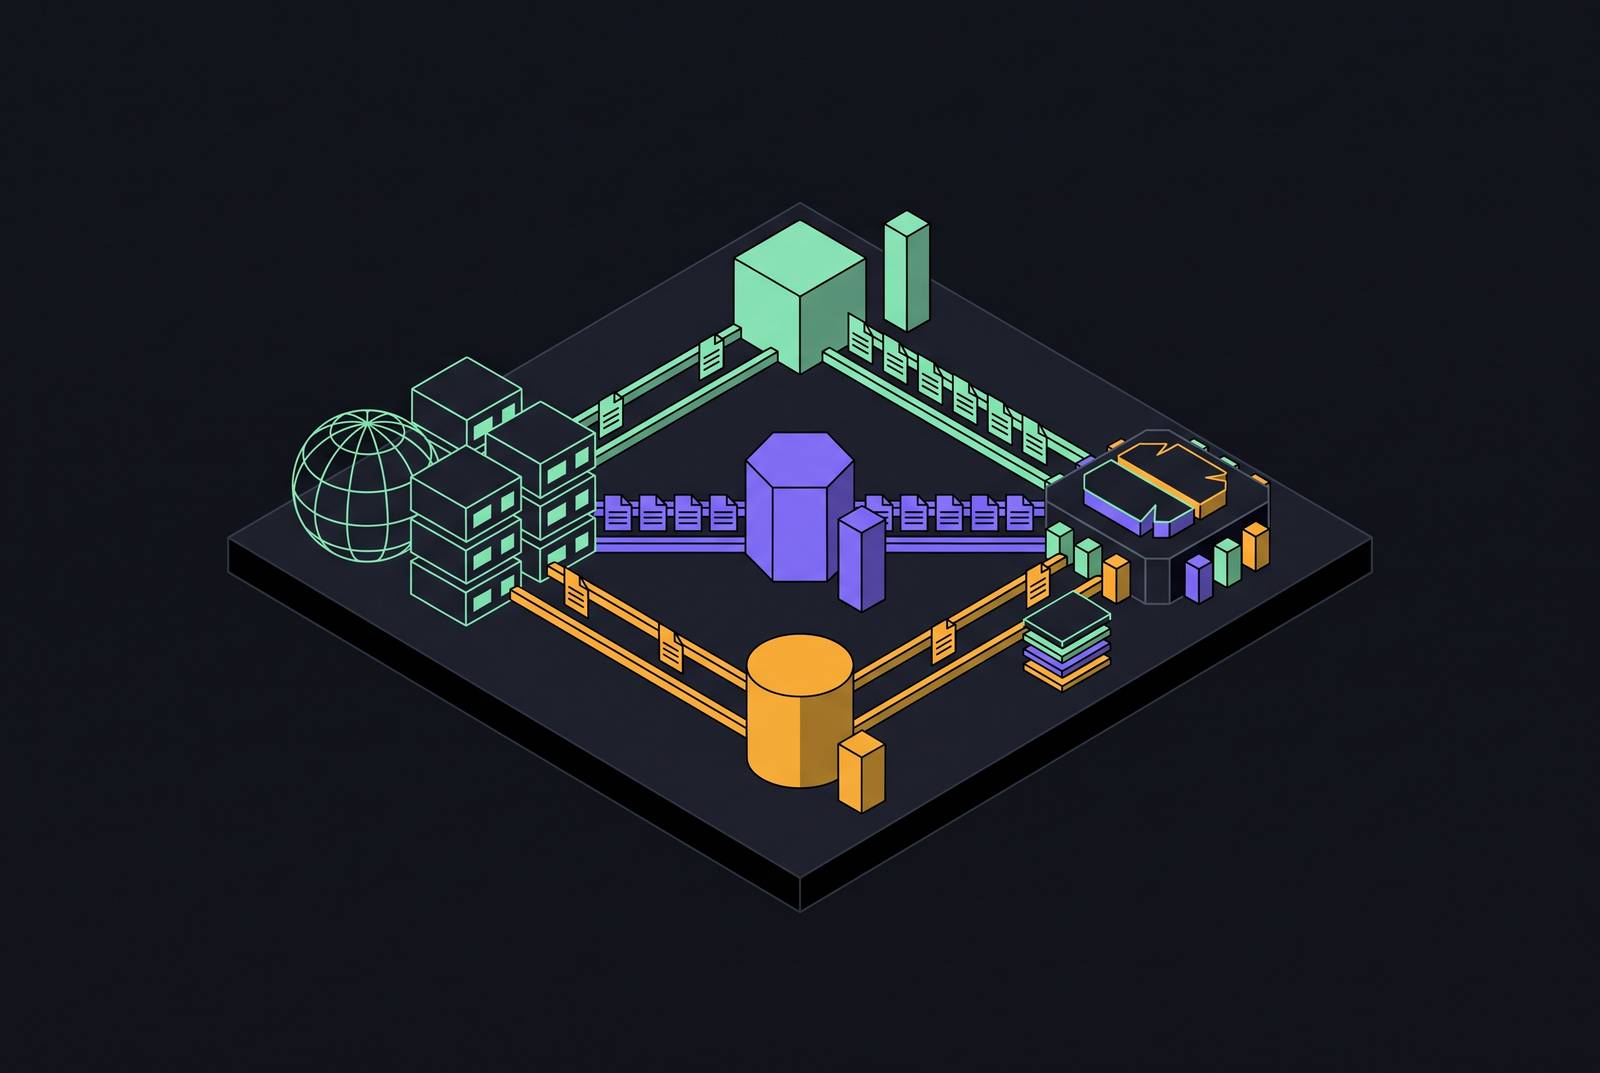
A web search API for AI agents and RAG pipelines should return usable evidence. AI-native retrieval is the better fit when a task needs clean content, sufficient retrieval depth, visible freshness, predictable latency, and citation metadata. SERP APIs serve ranking analysis, while scraping APIs support custom data acquisition.
Why RAG pipelines and autonomous agents impose different requirements on web search than traditional software does
A healthcare platform can receive a confident account of outdated treatment options from a model even when a significant new finding exists. The model’s training cutoff leaves that finding outside its learned knowledge, and the model cannot reliably signal the gap. Confidence is not a reliable indicator of currency. Web grounding puts current, cited content into the model’s context at query time, so the model has external evidence to draw on alongside its memorized weights.
That evidence enters two different retrieval patterns. In a RAG pipeline, search retrieves a document set once per query and passes it to the generative model. An autonomous agent can search more than once, with each result guiding whether it needs to search again and what it should ask. Where a human would click through and read, the application needs a retrieval path that supplies the underlying content.
How the web search API market has bifurcated around two incompatible design goals
Traditional SERP extraction and AI-native retrieval optimize for different outputs. SERP APIs reproduce what a human sees on a search engine results page, including organic rankings, ads, knowledge panels, and People Also Ask boxes. Their structured JSON can be used for rank tracking, competitive SEO, and marketplace monitoring. The results page itself is the product. Fidelity to that page is valuable even when the response does not contain the documents behind its links.
AI-native retrieval instead treats extracted, cleaned content as the product, so that a model can use it without a separate extraction stage. These are not competing versions of the same service. One preserves search-page presentation, while the other supplies evidence for generation. Web scraping APIs give developers a third option: control over how pages are acquired, but without the full search and ranking layer. That makes scraping a backend component for custom retrieval infrastructure.
The five production-grade dimensions that separate adequate from inadequate search APIs for AI workloads
Output structure comes first because it determines what reaches the model. Raw pages can contain 60–80% boilerplate, including navigation, ads, and cookie banners, which consumes tokens without supplying useful evidence. Clean Markdown or predictable JSON fields make the response easier to consume. Structure alone is not sufficient, however. Retrieval depth sets whether those fields hold short snippets, query-relevant excerpts, or full-page content that lets the model reason over longer passages.
Depth makes freshness consequential because even a complete document can ground an answer in obsolete facts. A cached page from last quarter may appear authoritative unless its age is visible. Fetch timestamps therefore need to travel with retrieved chunks, and recency-sensitive pipelines need signals that let them prefer newer sources. Publication dates and fetch timestamps serve different purposes. Together, they help distinguish when a source was published from when the retrieval system acquired it.
Freshness and depth also shape latency, the fourth dimension, because live acquisition takes place during the request while pre-extraction moves that work ahead of it. Agents amplify this distinction across successive tool calls. The fifth dimension, provenance, makes the resulting evidence auditable through source URLs, titles, and dates attached to content. A citation needs more than a plausible URL. The underlying text must be available so that downstream systems can verify whether the source supports the generated claim.
Where SERP APIs structurally fail AI workloads, and why the failure is architectural, not fixable with configuration
A SERP API can accurately reproduce search results while leaving an agent without enough evidence to answer. Its snippet is an introduction to a document. Getting the full content takes a separate fetch-and-parse request. That extra request adds latency and another point where things can fail, often because another vendor must be integrated. Changing result counts or response fields does not remove the distinction between discovering a page and acquiring its contents.
Fresh access to rankings also does not establish fresh access to the linked documents. Live SERP scraping preserves what the search engine returns, but it depends on infrastructure that faces anti-bot resistance. Since early 2025, Google and major web protection providers have strengthened interception based on behavioral patterns and browser fingerprinting. Simple proxy rotation is no longer enough. Reliable access at scale needs a large amount of proxy and anti-bot challenge-solving infrastructure, which makes the acquisition layer cost more to maintain.
Completeness creates another constraint when search engines display AI-generated answer blocks. An API that returns only organic results omits part of the page, which is consequential for an agent whose task is to understand what the engine actually surfaces. Third-party access also introduces procurement uncertainty because the scraping relationship can be contested technically and legally. These are properties of the access model. They limit the fit of SERP APIs as standalone evidence retrieval.
Where scraping APIs fall short as a standalone retrieval layer for production AI systems
Scraping APIs address page acquisition but do not, by themselves, decide which pages answer a question. The developer has to add query logic, deduplication, and relevance ranking. In a custom pipeline, responsibility can extend through fetching HTML, extracting text, embedding it into vectors, indexing it, and serving it to the model. Acquisition is only one stage of retrieval.
ScrapingBee positions its scraping API for developers building custom AI search infrastructure who need control over the data pipeline. That is a legitimate enterprise use case, as is acquiring content from a specific site or building a proprietary index. Direct page scrapers still face browser fingerprinting and behavioral detection, so they need rendering and proxy infrastructure to work reliably at scale. Combining scraping with SERP discovery adds both systems’ operational concerns. Each step can fail independently, while their latencies accumulate and two integrations need maintenance as usage grows.
Which search APIs are actually designed for RAG pipelines rather than just scraping SERPs?
AI-native retrieval APIs organize indexing, ranking, and response formatting around model consumption. Across output structure and retrieval depth, the structural difference is that search and extraction are combined. Responses contain cleaned Markdown or structured JSON with query-relevant passages or full-page content. Some providers offer adjustable retrieval depth. This lets a developer weigh how many tokens to use against how complete the evidence should be, without building a separate acquisition path.
For freshness, the AI-native approach pairs updated indices with fetch timestamps attached to retrieved chunks. Those signals let the application assess recency. Pre-indexing and pre-extraction can also reduce query-time latency because page processing happens before the request arrives. Content depth and freshness settings affect response time, so a fast shallow response is not directly comparable with a live, full-page retrieval.
Provenance comes with the response as structured source URLs, titles, and publication dates linked to the retrieved content. It supports citation-backed output without requiring the application to reconstruct attribution from raw HTML. The tradeoff is index fidelity versus live SERP fidelity. An AI-native index may be stale or incomplete, and retrieval relevance does not imply exact reproduction of live rankings. For agents that need precise ranking signals or local pack data, that difference is a real limitation.
How MCP integration is changing the way agents connect to web search at the infrastructure layer
Model Context Protocol, or MCP, is emerging as a standard way for compatible agents to discover and call search tools. With a direct API integration, the application controls request construction, response processing, and how content enters the model’s context. A hosted MCP server exposes tools through its own implementation. The available capabilities and configuration parameters therefore depend on what that server provides.
MCP also introduces a practical context-budget constraint because tool descriptions and returned search content both consume tokens. Teams evaluating it should limit enabled tools and control result length so that descriptions do not crowd out evidence. On-demand retrieval can keep current information at hand during a task without loading web context at initialization. The integration layer cannot repair weak retrieval. MCP availability and implementation quality belong in provider evaluation alongside latency, evidence depth, and output structure.
Enterprise considerations that go beyond retrieval quality: security, data ownership, and regulatory exposure
A technically capable provider can still fail enterprise procurement requirements. Queries, retrieved content, and any context passed through the API fall under both the provider’s data-handling policy and the customer’s privacy obligations. Enterprise teams should establish which model provider processes their data, on which service tier, and obtain retention and training terms in writing. A SOC 2 report alone is insufficient. Its Security and Confidentiality criteria address controls but do not necessarily disclose AI-specific details such as bias controls or decision-making explainability.
Regulatory obligations further constrain deployments that interact with customers. The European Commission states that Article 50 of the EU AI Act applies from 2 August 2026, when providers and deployers must comply with its transparency obligations. Teams that serve European users need to take those requirements into account when choosing a provider. Data location is a separate concern. Providers that can show they handle data in-region are better placed to meet data-sovereignty requirements than those that leave it unclear where and how they process data.
Data ownership also depends on the acquisition chain. A provider that controls crawling, indexing, extraction, and ranking offers a clearer provenance path than one that wraps another search engine. The latter adds upstream policies and the legal status of its access relationship to the customer’s risk assessment. Those dependencies extend beyond retrieval quality alone. If upstream access is contested, the application can face disruption even when the provider’s own endpoint and response format are technically sound.
How to evaluate providers against your actual workload rather than vendor benchmarks
Provider evaluation should begin by classifying the work as single-query RAG, iterative research, real-time fact-checking, or news monitoring. Each pattern weights the five dimensions differently, so an abstract quality ranking can conceal a poor operational fit. Vendor benchmarks also use different models, prompts, and sets of questions, so their scores cannot be reliably compared directly. The task distribution is the useful starting point. A comparison should test whether each provider can retrieve the evidence the application needs with the resources it has.
Cost should then be measured per correct answer. A cheap response can cost more when it needs extra extraction requests, cleaning downstream, or more tokens spent on boilerplate. Freshness needs an equally workload-specific test using sources from the actual domain. Major news coverage is not a sufficient proxy. A provider may retrieve mainstream reporting quickly while lagging on niche publications, regulatory filings, or technical documentation that a specialized agent depends on.
Latency testing should cover the complete agent task, including repeated searches and any content-acquisition steps. Teams can run two providers behind a router to compare response time, freshness, and answer accuracy on the same tasks before selecting a primary provider. Timeouts, partial failures, and empty results should be explicit test cases, with orchestration that handles them gracefully. Happy-path performance is only part of production behavior.