Memory and Retrieval Architecture in Long-Running AI Agents
Persistent memory architecture separates production AI agents from demos that fail in the field.
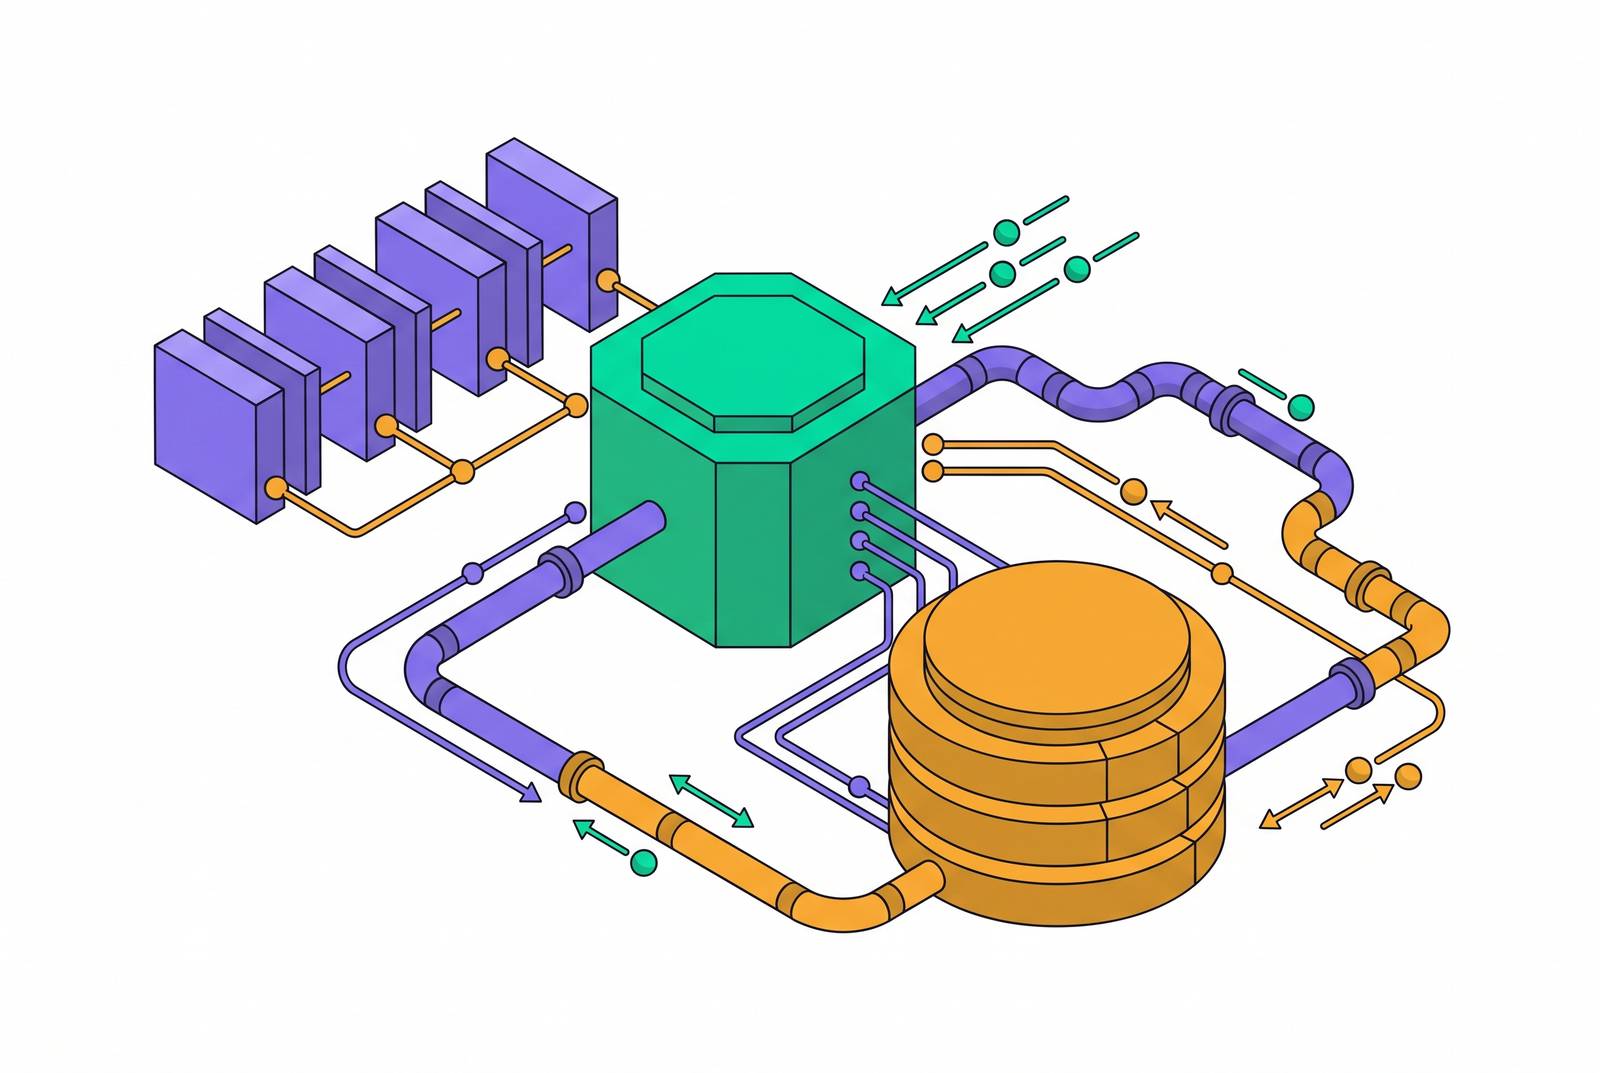
Memory in AI agents is a storage and retrieval problem with the same weight as a database schema decision, not a prompting trick to patch over a stateless model. Agents that fail in production usually fail for one reason: they forget things they were already told, and they forget in the same way every time. Understanding how memory is structured, stored, and retrieved is what separates agents that hold up across weeks of use from ones that reset to zero every session.
The demo produces the gap first: an agent handles a task well in a single sitting. An agent handles a task well in a single sitting, gets praised, gets deployed, and then a week later makes the same mistake it was corrected on during the pilot. The user re-explains the same preference. The agent re-asks a question it already had the answer to. This is not a model quality issue. Large language models are stateless by design: each call is a fresh computation over whatever tokens are in the context window, and when the session ends, that window is gone. Bigger context windows do not fix this, they just delay it. A context window is temporary and flat: every additional token raises cost and latency, and none of it persists once the session closes. Memory is a different kind of structure entirely: persistent, organized in layers, and built so that only the relevant sliver of a much larger history surfaces for any given query. A raw chat transcript is not memory either, it is a log that grows without bound. Memory is what gets distilled and structured out of that log so the agent can act on it later without re-reading everything.
The stakes are rising fast enough that this stops being an academic distinction. The AI agents market was valued at roughly $7.84 billion in 2025 and is projected to reach $52.62 billion by 2030, a 46.3% compound annual growth rate, according to figures from MarketsandMarkets and Grand View Research cited in Vektor Memory's "The State of AI Agent Memory in 2026." Mem0's State of AI Agent Memory 2026 report states that Gartner projects 40% of enterprise applications will integrate task-specific AI agents by the end of 2026, up from under 5% in 2025. McKinsey's State of AI survey found 23% of organizations already scaling an agentic system and another 39% experimenting with one. Most of that second group is going to hit persistence failures the moment they move past a pilot.
The four cognitive types of agent memory
The CoALA framework, published out of Princeton in 2023 (arXiv:2309.02427), gave the field a taxonomy borrowed from cognitive science, and it stuck. Letta, Mem0, and LangChain all build on some version of it. The taxonomy names four memory types, and they are not interchangeable pieces of the same bucket. Each stores something different, and each gets written to the system in a different way.
Working memory is the active context window, the material the model is reasoning over at this exact moment. It gets written implicitly just by the act of running a session, and it disappears the moment the session ends. Episodic memory is the record of what happened: past turns, past events, past interactions, logged automatically as raw material. Neither of these requires a deliberate design decision to exist. They're side effects of running the agent at all.
Semantic memory is where the deliberate engineering starts. It holds facts and accumulated understanding distilled out of episodes, such as a user's job title, a company's approval threshold, and a vendor's preferred invoice format. None of that gets extracted for free. It requires a background process that reads the raw logs and turns them into structured, retrievable facts. Skip that step and the agent has history but no knowledge.
Procedural memory sits one layer above semantic memory, holding the rules, the behavioral instructions, the "how to do this job correctly" material that makes an agent better at its work rather than just more informed about the world. It holds the rules, the behavioral instructions, the "how to do this job correctly" material that makes an agent better at its work rather than just more informed about the world. Mem0's State of AI Agent Memory report describes tooling for managing procedural memory as still early-stage across the industry. That immaturity is an opportunity: teams that design procedural memory on purpose, rather than letting it accumulate as an implicit byproduct of episodic logs, end up with agents that visibly improve over time instead of agents that just remember more without getting sharper.
The taxonomy also exposes a split that's easy to miss when memory gets talked about as one undifferentiated feature. Personalization, built from episodic and semantic memory about a specific user, is the problem most teams notice first, because it's the one users complain about loudest ("why did it forget my preference"). Institutional knowledge, built from procedural memory and semantic memory about domain rules and accumulated corrections, is the harder and more valuable problem, because it compounds across every run of the agent rather than resetting with each user.
Consider a procurement agent that gets corrected on day one: use vendor X's specific invoice format, route anything over $50,000 through a second approval step, and account for the fact that the department is over budget heading into Q4. If those three corrections vanish at the end of the session, the underlying model simply lacks a place for procedural and semantic memory to persist. It's failing because procedural memory and semantic memory were never given a place to live.
Storage architectures: capabilities and limits of vectors, graphs, and hybrids
Storage architecture is not a commodity decision made after the "real" design work is done. It determines which retrieval strategies are even available later, what ingesting new information costs, and how the system behaves when two stored facts contradict each other. Three approaches dominate production systems as of 2026, and each one trades away something to get its strengths.
Vector-first storage retrieves by semantic similarity between embeddings. It's fast, it's the most broadly compatible approach across tooling, and it's the default most teams reach for first. Its weakness is structural: pure vector search misses exact keyword matches, and it struggles badly with multi-hop questions that require chaining several related facts together rather than finding one close match.
Knowledge-graph-first storage, the approach Cognee takes, builds a knowledge graph directly from raw data as the primary retrieval mechanism rather than bolting a graph on top of a vector store as an afterthought. It is best suited to knowledge-graph-first retrieval-augmented-generation workflows, and it's open-source and self-hostable. Hybrid vector-plus-graph storage, the pattern Zep and Mem0 both use, combines semantic vector retrieval with explicit tracking of entities and relationships. Zep's version is a temporal knowledge graph specifically, and it's the strongest of the three approaches on temporal reasoning tasks, where "when did this become true" matters as much as "is this true."
A 2026 entrant complicates the assumption that hybrid graph-vector systems are the ceiling for quality. Memanto, built on an information-theoretic search engine called Moorcheh, uses a typed memory schema with thirteen semantic categories and built-in conflict resolution. It demonstrates that a sufficiently optimized semantic retrieval layer can match or beat hybrid graph-vector architectures while cutting retrieval down to a single query, removing the multi-query overhead that graph traversal usually requires, and dropping the schema-management burden that graph layers carry. That doesn't mean graph layers are obsolete, but it does mean the assumption that a graph is always necessary for quality retrieval no longer holds unchallenged.
Two more recent frameworks address different edges of the same problem. TiMem, from Li et al. in 2026, introduces a temporal-hierarchical memory framework built around a structure called a Temporal Memory Tree, aimed at consolidating long interaction histories into scalable, structured personalization without needing fine-tuning. And on pure efficiency, research into compounding memory architectures has shown a 7-billion-parameter model outperforming a 32-billion-parameter baseline by 18%, a signal that architecture-level memory design is a lever for cutting inference cost, not just a lever for accuracy.
Curation is the problem underneath all three architectural families, and storage choice alone doesn't solve it. A system that just appends new memories without reconciling them against what's already stored accumulates contradictions quietly. Retrieval quality doesn't fail all at once, it erodes, as the agent starts surfacing two conflicting beliefs about the same fact and has no principled way to pick between them.
The tooling landscape reflects these trade-offs directly. Mem0 runs hybrid vector-plus-metadata filtering with built-in version control, offered as both managed cloud and self-hosted, under Apache 2.0, with roughly 48,000 GitHub stars. Letta, the MemGPT lineage, borrows an operating-system model of virtual context management, moving information between in-context and long-term storage, also Apache 2.0, around 21,000 stars. Zep and its open-source Graphiti engine lead on temporal reasoning specifically, at roughly 24,000 stars. Cognee, graph-first and self-hostable, is around 12,000 stars. Hindsight runs a multi-strategy hybrid built for institutional memory under an MIT license, around 4,000 stars. SuperMemory handles personalization and some institutional memory but is managed-cloud only, with no self-hosting option. One personalization-focused framework uses flat JSON key-value storage and vector similarity retrieval, storage-agnostic, released under a permissive open-source license, built to plug into LangGraph. LlamaIndex Memory offers composable memory buffers as part of the broader LlamaIndex ecosystem, also MIT.
Cloudflare's Agent Memory service, in private beta as of April 2026, has not earned production-dependency status yet, so it should be watched rather than adopted outright. It's a managed service built around the extraction-and-retrieval pattern, aimed at Workers workloads, but it hasn't earned production-dependency status yet. Anyone evaluating it should hold it to the same latency, accuracy, cost, and portability tests as the dedicated memory layers above, not wave it through on Cloudflare's name alone.
How retrieval works inside a memory layer, and why latency is an architectural constraint not an optimization detail
The standard retrieval pattern runs once per turn, outside the model's reasoning loop. At the start of a session, or at the start of a turn, the system pulls relevant memories by some combination of semantic similarity, keyword matching, and entity matching, then stuffs the result into the context window before the model generates a response. Retrieval happens once, upstream of reasoning, not inside it.
A 2026 paper by Khan and Lipizzi (arXiv:2607.05690) challenges that pattern directly, proposing that memory reads and writes move inside the reasoning loop itself, firing on every reasoning step rather than once per turn. The obvious objection is latency: a networked vector store typically answers in 50 to 200 milliseconds, and paying that cost on every single reasoning step, rather than once per turn, sounds prohibitive on its face.
The paper's actual finding undercuts that objection. Latency, it turns out, is a property of where the memory store physically lives, not a property of the retrieval pattern itself. An in-process store, one that lives in the same memory space as the agent rather than across a network call, answers in roughly 100 microseconds, which collapses the supposed cost of per-step retrieval by three orders of magnitude. The causal test holding the per-turn memory budget fixed and varying only how fast the store answers shows redundant actions rise monotonically from 0 out of 12 at in-process speed to 7.2 out of 12 at a 110-millisecond round trip, across two models, with the difference statistically significant at an exact permutation p-value of 0.0079. Slower retrieval doesn't just feel worse. It measurably causes the agent to repeat itself.
Recall numbers tell the same story from a different angle. A bounded context window alone drives recall to 0 out of 5 across four GPT-5-class models tested, meaning without a memory mechanism, none of them reliably retrieve information from earlier in a long interaction. In-loop memory recovers recall to somewhere between 3.6 and 4.8 out of 5, and the paper traces the remaining misses to the agent's read policy, how and when it chooses to query, rather than to any limitation of the store itself. Adding a deduplication gate on the write side (filtering out redundant writes before they ever hit storage) pushes recall up to between 4.8 and 5.0 out of 5.
Cost matters here too, not just accuracy. By turn 25 in the paper's testing, the gated in-process store comes out cheaper than a restating baseline on every model tested, at equal judged accuracy. And the last bottleneck standing is the embedding step itself: a networked embedding call runs 200 to 400 milliseconds, but a local embedder brings the full read-write operation down to roughly 40 microseconds.
None of this replaces the value of combining retrieval signals. Pure vector search misses exact keyword hits, pure keyword search misses semantic near-matches, and production memory layers that combine semantic similarity, keyword matching, and entity matching outperform any single method alone, the same hybrid-retrieval principle that already governs document-level RAG applies just as directly to memory.
Scale changes the picture further. Mem0's BEAM benchmark tests memory systems at token scales orders of magnitude past what benchmarks like LoCoMo cover, and a system that scores well on the smaller benchmark does not automatically hold that performance once the token volume grows that large. Mem0's own 2026 algorithm scores 92.5 on LoCoMo and 94.4 on LongMemEval, using approximately 6,956 and 6,787 tokens per query respectively. Those per-query token counts matter for production cost modeling every bit as much as the accuracy score does: a system that's marginally more accurate but burns twice the tokens per query is not obviously the better production choice.
The benchmark landscape for evaluating memory systems: what LoCoMo, LongMemEval, and BEAM measure
Mem0's State of AI Agent Memory 2026 report states that three benchmarks now define how memory systems get measured, and they test genuinely different failure modes rather than the same thing at different sizes.
LoCoMo runs 1,540 questions across four categories: single-hop, multi-hop, open-domain, and temporal reasoning, testing recall across conversational data that spans multiple sessions. Before LoCoMo existed as a reproducible baseline, memory quality claims in the field were mostly self-reported, which is another way of saying mostly unverifiable. LongMemEval runs 500 questions across six categories, and it's particularly punishing on the knowledge-update and multi-session categories specifically, the ones that require noticing a fact has changed. BEAM operates at a token scale far beyond what context-window expansion alone can substitute for, making it relevant for production-scale evaluation. It covers ten categories: preference following, instruction following, information extraction, knowledge update, multi-session reasoning, summarization, temporal reasoning, event ordering, contradiction resolution, and abstention.
The evaluation methodology across these benchmarks also runs five dimensions rather than one, which matters because optimizing for a single axis produces systems that look great on paper and fall apart in deployment. The five are a token-level similarity score measured against a reference answer, F1 (precision and recall combined), a large-model judge score for binary correctness, token consumption per query, and wall-clock latency. A system that posts a high accuracy number while burning far more tokens per query than a competitor isn't actually the stronger production choice, it's just the more expensive one dressed up as the better one.
Mem0's 2026 algorithm posts 92.5 on LoCoMo, 94.4 on LongMemEval, 64.1 on BEAM at the 1-million-token scale, and 48.6 on BEAM at the 10-million-token scale. That drop from the low-to-mid-90s down into the 60s and then the 40s as scale increases is the honest finding here: even the best measured system today degrades meaningfully once token volume reaches production scale. Anyone reading a benchmark score without checking which benchmark it came from is reading half the story.
The two categories where Mem0's new algorithm gained the most ground over its prior version were temporal reasoning, up 29.6 points, and multi-hop reasoning, up 23.1 points. Those are the two categories that most directly test skills real user histories require. They're the two that most directly mirror how real user histories actually behave: facts pile up, facts change, and facts relate to other facts learned somewhere else entirely.
Even with that progress, Mem0's 2026 report is explicit that cross-session identity resolution, temporal abstraction at scale, and memory staleness remain unsolved. Separately, Atlan's analysis of independent benchmarks points to as much as a 15-point accuracy gap between architectures specifically on temporal queries, a gap wide enough to reflect a real architectural divide between systems rather than a tuning difference that better hyperparameters would close.
Temporal reasoning and memory staleness: the two hardest open problems in production memory systems
Temporal reasoning is the benchmark category that maps most directly onto how agents actually fail in the field. User facts accumulate over time, sometimes contradict earlier facts, and sometimes simply go out of date, and a memory system with no sense of time will serve up a stale answer with the same confidence as a current one. The 29.6-point jump in Mem0's 2026 algorithm on exactly this category is a real gain, but the size of the jump also says something about how far behind the prior generation of systems was starting from.
Staleness and decay get talked about as though they're the same problem, and they aren't. Decay is the easy case: once a memory loses relevance, retrieval for it simply falls off, and the system degrades gracefully because nobody's asking for that fact anymore. Staleness in a high-relevance memory is the hard case, and it's the one still unsolved. A memory about where a user works might get retrieved constantly, accurately, for months, right up until the user changes jobs, at which point the memory is not just wrong, it's confidently wrong, and the very reliability that made it useful before is what makes the error dangerous now. No framework currently on the market has solved automated staleness detection for memories that are both high-confidence and high-retrieval. That's not a minor gap, it's the gap.
Mem0's 2026 report identifies cross-session identity resolution alongside staleness as one of the field's hardest remaining problems. The same person, the same vendor, the same project can show up across different sessions under different names or references, and the memory system has to correctly decide whether two mentions refer to the same entity or two different ones. Get that wrong and either memories merge that shouldn't, or memories that should connect never do. The 23.1-point gain on multi-hop reasoning is related territory: it reflects an agent's ability to chain facts learned in separate sessions, possibly filed under different entities, into a single coherent answer.
The practical takeaway for anyone building on top of these systems is that a memory architecture designed only to append facts is not enough. It needs an explicit path for updating a fact and resolving a conflict between an old fact and a new one, not just a path for storing something new next to something old and hoping retrieval sorts it out. This is where the frameworks covered above actually diverge most from each other, in how deliberately they've built that update-and-reconcile path versus leaving it as an implicit side effect of more storage.
Khan and Lipizzi's write-side dedup finding (arXiv:2607.05690) is a useful model for how to approach this kind of problem generally. Rather than assuming a recall failure means the memory store itself is broken, the diagnostic step was to check whether the failure came from the store or from the agent's read policy, how and when it chose to query. That diagnosis pointed to a targeted fix on the write side, and the fix moved recall from a range of 3.6 to 4.8 out of 5 up to 4.8 to 5.0 out of 5. The lesson generalizes past this one paper: fixing a memory system starts with figuring out which side of the read-write boundary is actually failing, not with reaching for a bigger store or a fancier retrieval algorithm on instinct.
Sources
- Best AI Agent Memory Systems in 2026: 8 Frameworks Compared
- The State of AI Agent Memory in 2026: What the Research Actually Shows | by Vektor Memory | Medium
- State of AI Agent Memory 2026: Benchmarks & Trends
- Memory in the Loop: In-Process Retrieval as Extended Working Memory for Language Agents
- Memanto: Typed Semantic Memory with Information-Theoretic Retrieval for Long-Horizon Agents