Data Provenance and Lineage Tracking in Web Knowledge Pipelines
Tracking where AI systems source their answers prevents hallucination and satisfies audits.
Devin Matsukawa
Contributing Editor
Devin has reported on web infrastructure and open-data ecosystems since the early RSS era, with bylines across developer-focused outlets before joining this publication. He focuses on how live web knowledge flows into AI systems, including crawling ethics, freshness tradeoffs, and the evolving landscape of web retrieval tooling.
6 stories
Tracking where AI systems source their answers prevents hallucination and satisfies audits.
Current benchmarks hide whether failures stem from reasoning, planning, or outdated web content.
One query fans out into dozens of API calls, turning cost control into a core engineering challenge.
Shared retrieval layer quality sets the performance ceiling for every agent that depends on it.
Embedding model choice matters more than benchmark scores for web-grounded RAG.
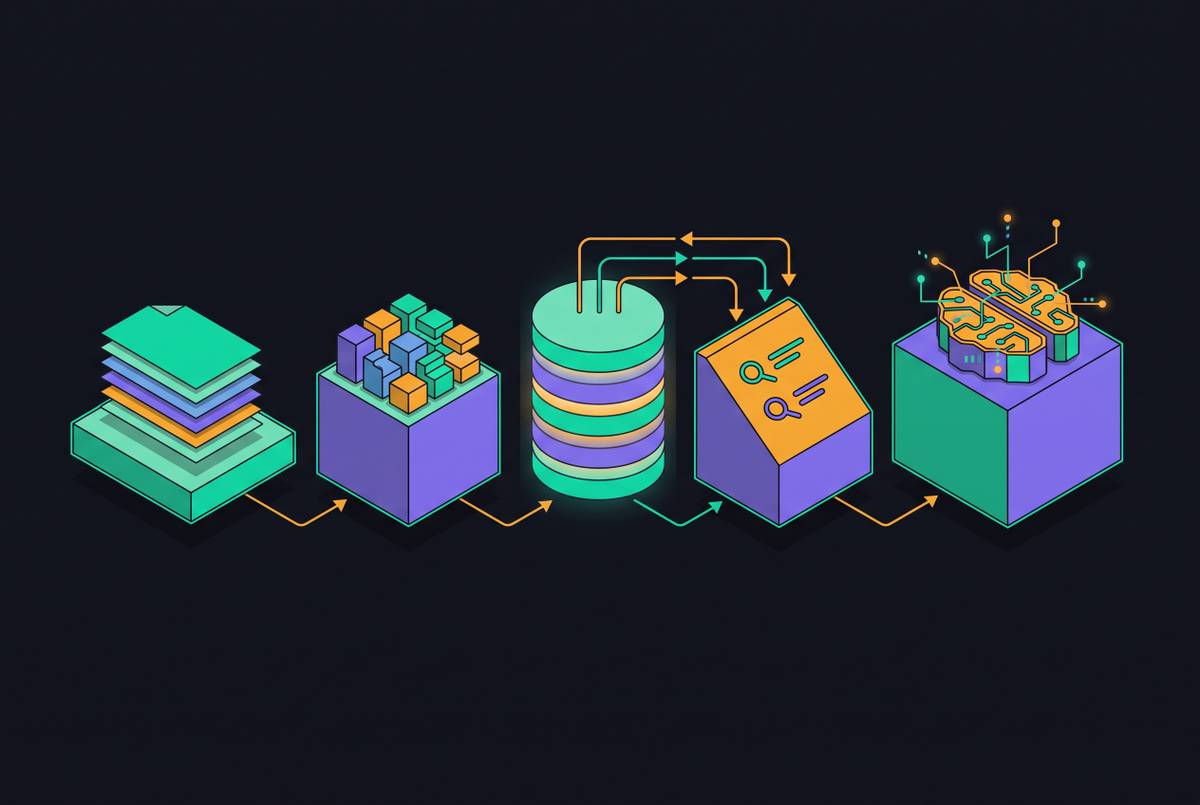
Retrieval breakdowns, not model failures, cause most production RAG systems to fail silently.